TL;DR for operators
A RAG system can return the right answer, attach a source that genuinely supports that answer, and still leave one critical question unresolved: did that source actually influence the model’s answer generation?
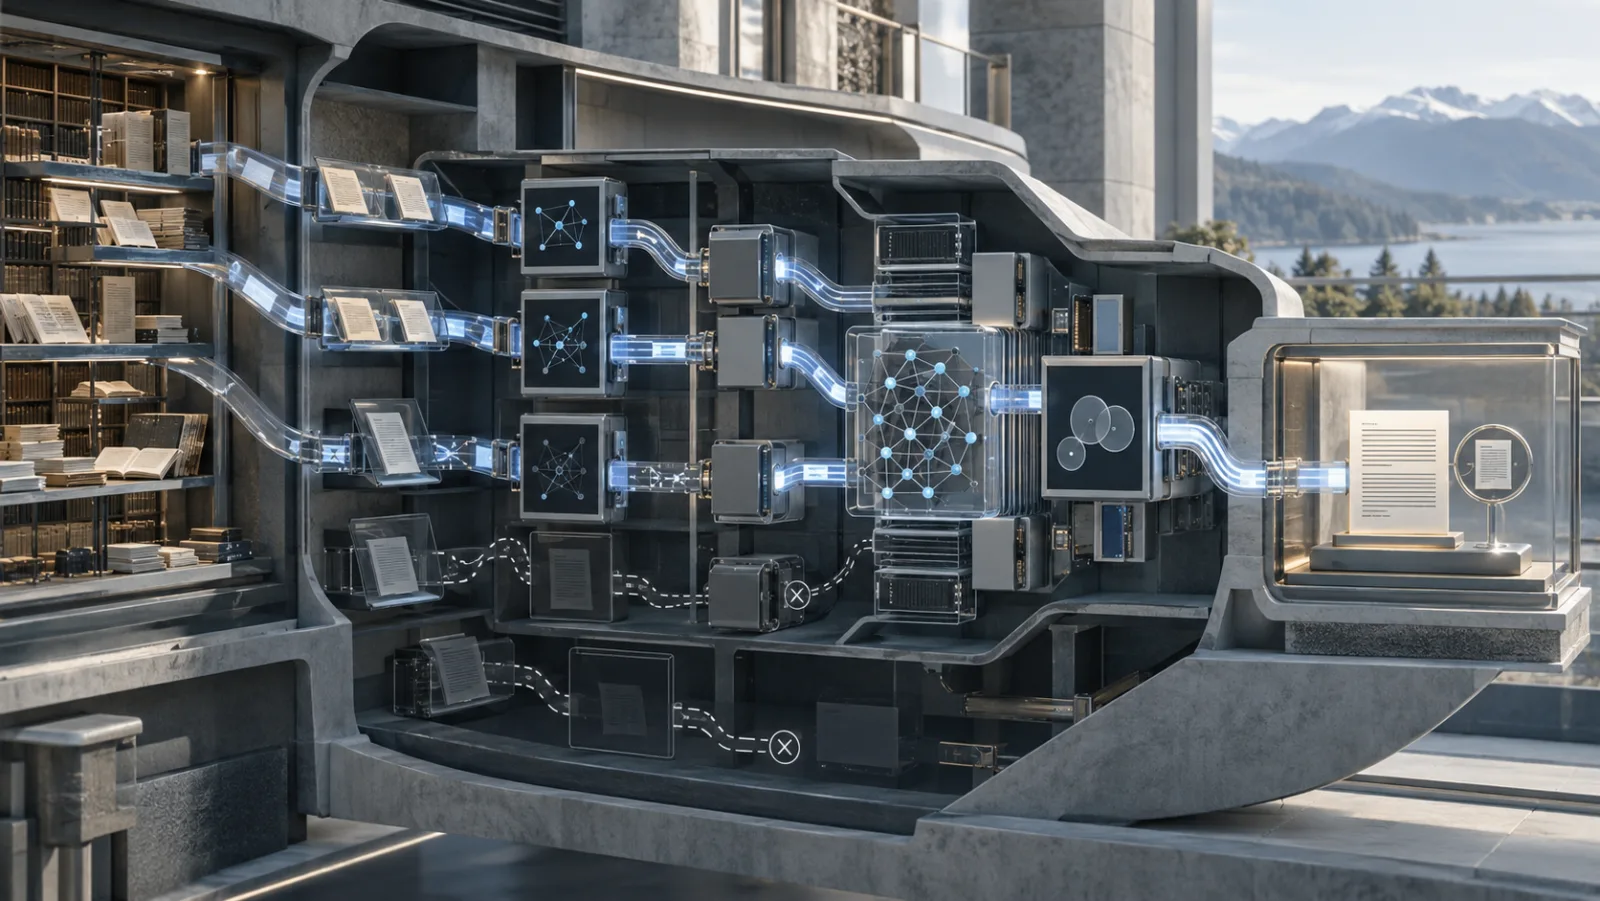
A mechanistic study of Llama-3.1-8B-Instruct finds that inline citation behavior is not controlled by one dedicated citation feature. It emerges from a distributed sequence of attention heads and MLPs that includes early entity enrichment, matching between document and question entities, mid-layer processing, and late aggregation that shifts the model toward emitting a citation marker rather than ending the sentence.1
That mechanism is experimentally controllable. In targeted PopQA failure cases, amplifying identified pro-citation components repaired more than 90% of missed citations with negligible impact on answer-token correctness. Attenuating necessary components suppressed 9 of 13 observed spurious citations. But more citation pressure is not automatically better: stronger amplification across the broader PopQA distribution also increased some citations when the supplied document was irrelevant.
The operating consequence is to stop treating citation presence as a proxy for grounding. Track answer correctness, citation correctness, spurious citation behavior, and evidence that the source actually influenced generation as distinct properties. Mechanistic controls are promising as a future diagnostic or steering layer, but the paper does not establish production-ready citation faithfulness across models or complex RAG pipelines.
A supporting citation does not tell you where the answer came from
The familiar RAG success case is visually persuasive. A user asks a question, the system returns a correct answer, and an inline source points to a passage that supports it.
That establishes compatibility between answer and source. It does not establish provenance of the model’s computation.
A model may already possess the fact in its parameters, generate the answer from that internal knowledge, and then produce a citation because the retrieved document looks relevant. In that case the citation is correct in the ordinary sense, but it does not demonstrate that retrieval caused the answer.
This distinction motivates the paper’s use of citation faithfulness: whether the cited document actually influenced the model’s internal generation process, rather than merely agreeing with the final response.
For a product team, the difference matters because source-linked interfaces often communicate more certainty than output-level evaluation can justify. A verified source may prove that an answer has external support. It does not, by itself, prove that the model grounded its reasoning in that source.
Citation behavior is assembled across several stages
To investigate the internal decision, the authors compare matched runs in which the question and prompt remain fixed while the supplied document changes between a relevant supporting passage and a structure-matched distractor.
They then use activation patching: internal activations from one condition are inserted into the other to test which components causally move the model’s immediate preference between starting a citation and ending the sentence with a period.
The main localization result is distributed rather than modular.
Early in the network, an MLP appears to enrich representations of entities in the supplied document. When the same entity appears in the question, that enriched representation contributes to a cross-context identity or duplication signal. A denser middle region of attention heads and MLPs then processes the signal, while later components aggregate citation-relevant evidence at the answer position.
The components also behave approximately conjunctively. Corrupting one important component can remove a large share of citation behavior—a representative mid-layer attention head removes more than 60% in the reported analysis—while restoring a single component usually recovers much less, typically around 10–30%.
That asymmetry matters. The paper is not identifying a “citation head” that independently switches citations on or off. It is locating members of a distributed ensemble whose joint state helps determine whether the model emits a citation.
It also sharpens the faithfulness concern. Entity correspondence is a meaningful relevance cue, but it is weaker evidence than demonstrating that the answer itself was computed from the cited passage. The authors therefore interpret the mechanism as compatible with citation generation running partly in parallel to answer construction.
They do not prove that the two processes are completely separate; the answer-generation circuit is not independently mapped.
The mechanistic map becomes a control surface
Localization alone would show where citation behavior changes. The stronger evidence comes from manipulating the identified components afterward.
In targeted missed-citation cases, amplifying components with importance above 0.10 using a scaling factor of $\alpha=1.2$ repaired more than 90% of the missed citations, while having negligible impact on answer-token correctness.
The complementary test addresses excessive citation. Down-scaling necessary components at an importance threshold of 0.20 and $\alpha=0.6$ suppressed 9 of 13 observed spurious citations, or 69%, with only a minor decline in factual correctness.
These experiments serve a different purpose from the initial activation-patching analysis. Patching is the main component-localization evidence. Scaling is an intervention test showing that those localized components can causally steer the behavior the analysis attributes to them.
The broader PopQA intervention is then a distribution-level test rather than another discovery experiment. A unified amplification at $\alpha=1.1$ produced the best combined success metric. Increasing activation further could induce additional citations even when the document was irrelevant.
That trade-off is central to operational use. A system that simply increases citation propensity can improve one metric while degrading another. Citation control therefore needs separate measures for missing attribution and inappropriate attribution.
HotpotQA shows transfer, but not deployment-level reliability
The authors next apply the same component set, without retuning, to 6,808 HotpotQA examples. This is the paper’s strongest evidence that the intervention is not confined to the controlled PopQA localization cases.
The direction of effect transfers.
At $\alpha=1.2$, strict correct-citation rate rises from 0.001 to 0.024. At $\alpha=1.3$, joint answer-and-correct-citation performance rises from 4 of 6,808 examples to 124 of 6,808, while answer-string correctness increases from 0.55 to 0.64.
Those relative gains are substantial. The absolute citation result is still weak: a strict correct-citation rate of 0.024 is nowhere near a production reliability threshold for a system whose interface asks users to trust source attribution.
Formatting near-misses may cause the metric to undercount some useful behavior, but that does not erase the central boundary. The transfer result supports directional generalization of the control mechanism. It does not establish high-quality multi-document citation generation.
RAG evaluation should separate four questions
The paper directly studies one model and one citation mechanism. The following operating framework is a Cognaptus inference from that evidence, not a benchmark proposed by the authors.
| Evaluation question | What it asks | Why it should be separate |
|---|---|---|
| Is the answer correct? | Did the system return the right content? | A correct answer can come from retrieval, parametric memory, or another pathway. |
| Is the citation correct? | Does the cited source support the claim? | Entailment does not establish causal use of the source. |
| Is the citation appropriate? | Did the system avoid citing irrelevant material? | Increasing citation propensity can also increase spurious citations. |
| Is the citation faithful? | Did the source actually influence generation? | This is the property that a plausible source marker cannot establish from output alone. |
For high-stakes knowledge products, this changes the role of the citation UI. A citation should be treated as an attribution claim generated by the system, not as self-authenticating evidence that retrieval worked as intended.
The same distinction affects governance. A team may reasonably validate answer quality and source support at scale using output-level checks. If it wants to claim that answers are grounded in supplied evidence, it needs a stronger validation story than source compatibility alone.
Mechanistic auditing is one possible future layer. This paper shows that internal citation-related components can be identified and manipulated in a controlled setting. It does not yet show that such controls are stable across architectures, model sizes, RAG fine-tuning regimes, or production retrieval stacks.
The current boundary is node-level control, not a complete citation circuit
Three limitations constrain how far to carry the result.
First, all mechanistic localization is performed on Llama-3.1-8B-Instruct. Whether other models implement citation decisions through similar components is unresolved.
Second, the primary experiment is deliberately controlled and largely single-document. HotpotQA provides a harder multi-document transfer test, but its low absolute strict-citation accuracy shows that successful direction of effect is not equivalent to reliable attribution.
Third, activation patching identifies causally influential internal nodes but does not reconstruct the directed paths between them. The paper points to path patching as a next step. Without that connectivity—and without separately mapping the answer-generation computation—the study cannot fully determine how much citation generation overlaps with the mechanism producing the answer.
The result is therefore narrower, and more useful, than a claim that mechanistic interpretability has solved RAG attribution. It shows that citation emission itself has an identifiable causal structure, that parts of that structure can be steered, and that visible citations may be driven by signals weaker than faithful dependence on retrieved evidence.
For RAG operators, that is enough to revise one assumption: a citation marker is an output to evaluate, not proof of grounding by itself.
Cognaptus: Automate the Present, Incubate the Future.
-
Ian van Dort and Maria Heuss (2026). How Do LLMs Cite? A Mechanistic Interpretation of Attribution in Retrieval-Augmented Generation. arXiv:2606.28358. https://arxiv.org/abs/2606.28358 ↩︎