The Next Image Changes the Search: Why Visual Agents Need Better Retrievers
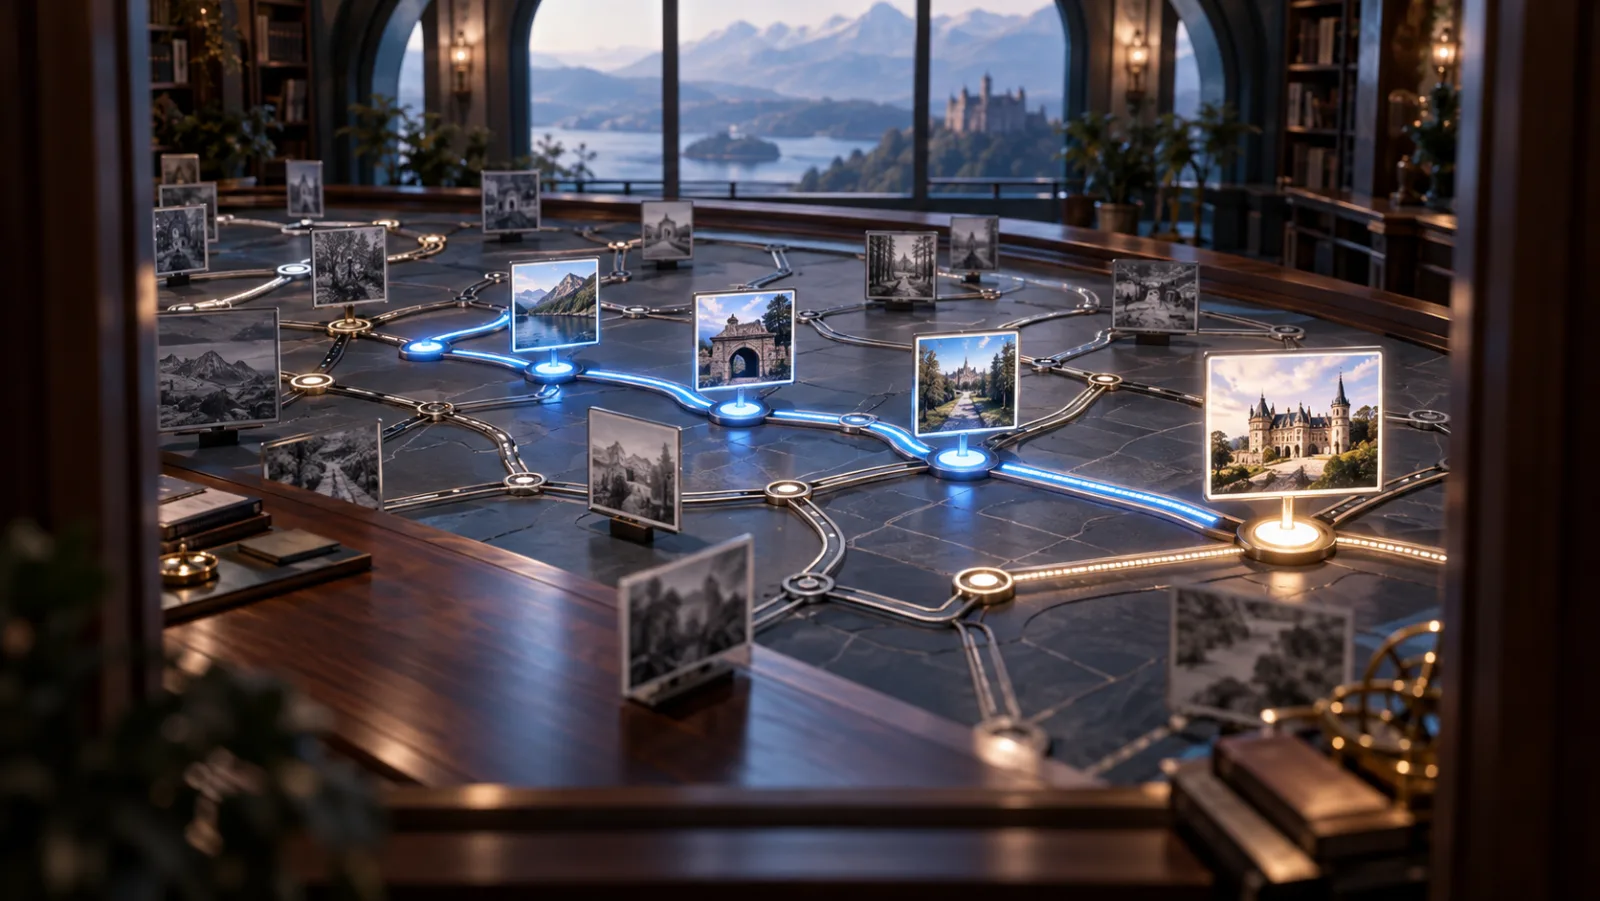
TL;DR for operators A multimodal agent may fail to find an image because the necessary evidence emerges only after several dependent searches. Upgrading its language model does not necessarily resolve that retrieval bottleneck. Chen, Zhou, and Wu’s VHop-Router1 moves sequential image selection, backtracking, and stopping into the retrieval tool itself. On 300 held-out three-hop visual-search questions, upgrading retrieval improves agent success from 32.7% to 85.4%, a 52.7-percentage-point gain. Upgrading the agent while retaining conventional retrieval produces only a small improvement. ...