Reward the Claim, Not Just the Answer: What V-Rubrics Changes in Multimodal RL
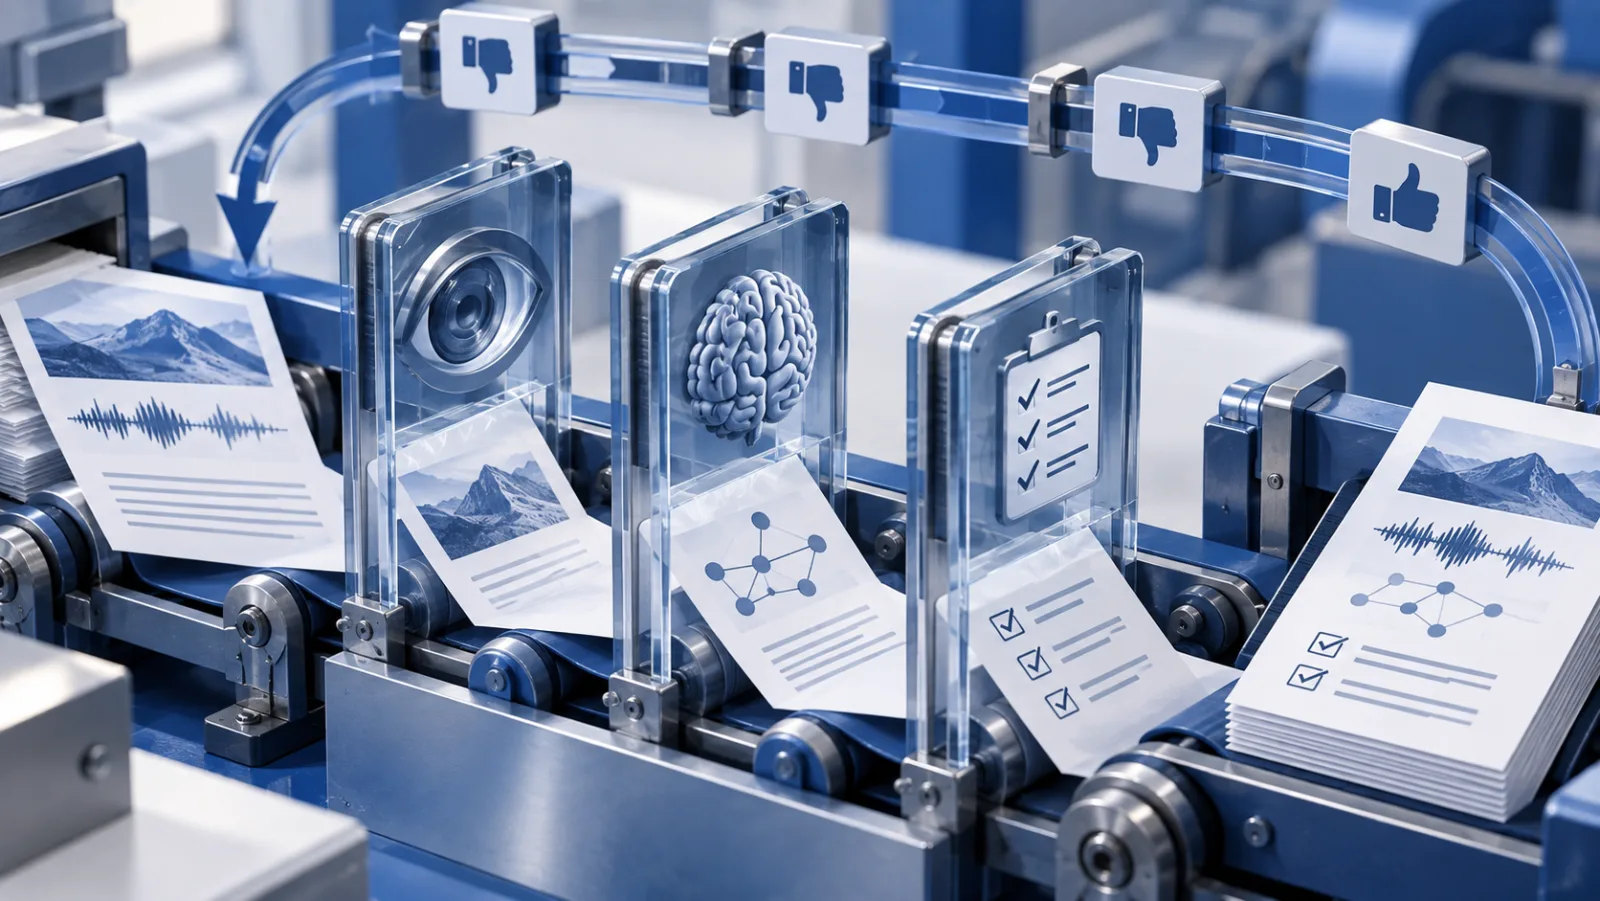
TL;DR for operators If a multimodal model reaches the correct final answer after misreading part of an image or making an invalid intermediate inference, a binary success reward gives the optimizer little information about what should actually be reinforced. The paper studied here turns those failure classes into separate training signals and, where possible, assigns their reinforcement-learning credit only to the relevant portion of the response. ...