Cover image

Clean Speech Is a Prior, Not a Finish Line

TL;DR for operators Kammoun, Leglaive, Alameda-Pineda, and Gerkmann propose a source-free way to adapt a pretrained speech-enhancement model to one noisy utterance at inference time.1 The system uses one second of unlabeled deployment audio and a separately trained model of clean speech as its adaptation signal. It resets the enhancement model to its pretrained parameters before each new utterance, so adaptation is local rather than cumulative. ...
October 9, 2026 · 7 min · Zelina
Cover image

Rotate Before You Update: Deeper Test-Time Adaptation for Graph Models

TL;DR for operators A deployed graph model may encounter a new network, molecule population, or sensor regime and still need to predict before any verified label exists. The operational question is whether it should remain fixed or make a tightly bounded adjustment using only information available in the incoming unlabeled sample. T3R offers the second option. Across nine DiTEC-WDN benchmarks, one update reduced average RMSE from 0.5023 under ERM to 0.3095, a 38.38% reduction, although it did not lead the average NSE metric. The method learns during training how an auxiliary objective can provide proxy updates for deeper prediction layers when the true supervised correction is unavailable. ...

July 24, 2026 · 8 min · Zelina
Cover image

Rules of Engagement: How Meta‑Policy Reflexion Turns Agent Memory into Guardrails

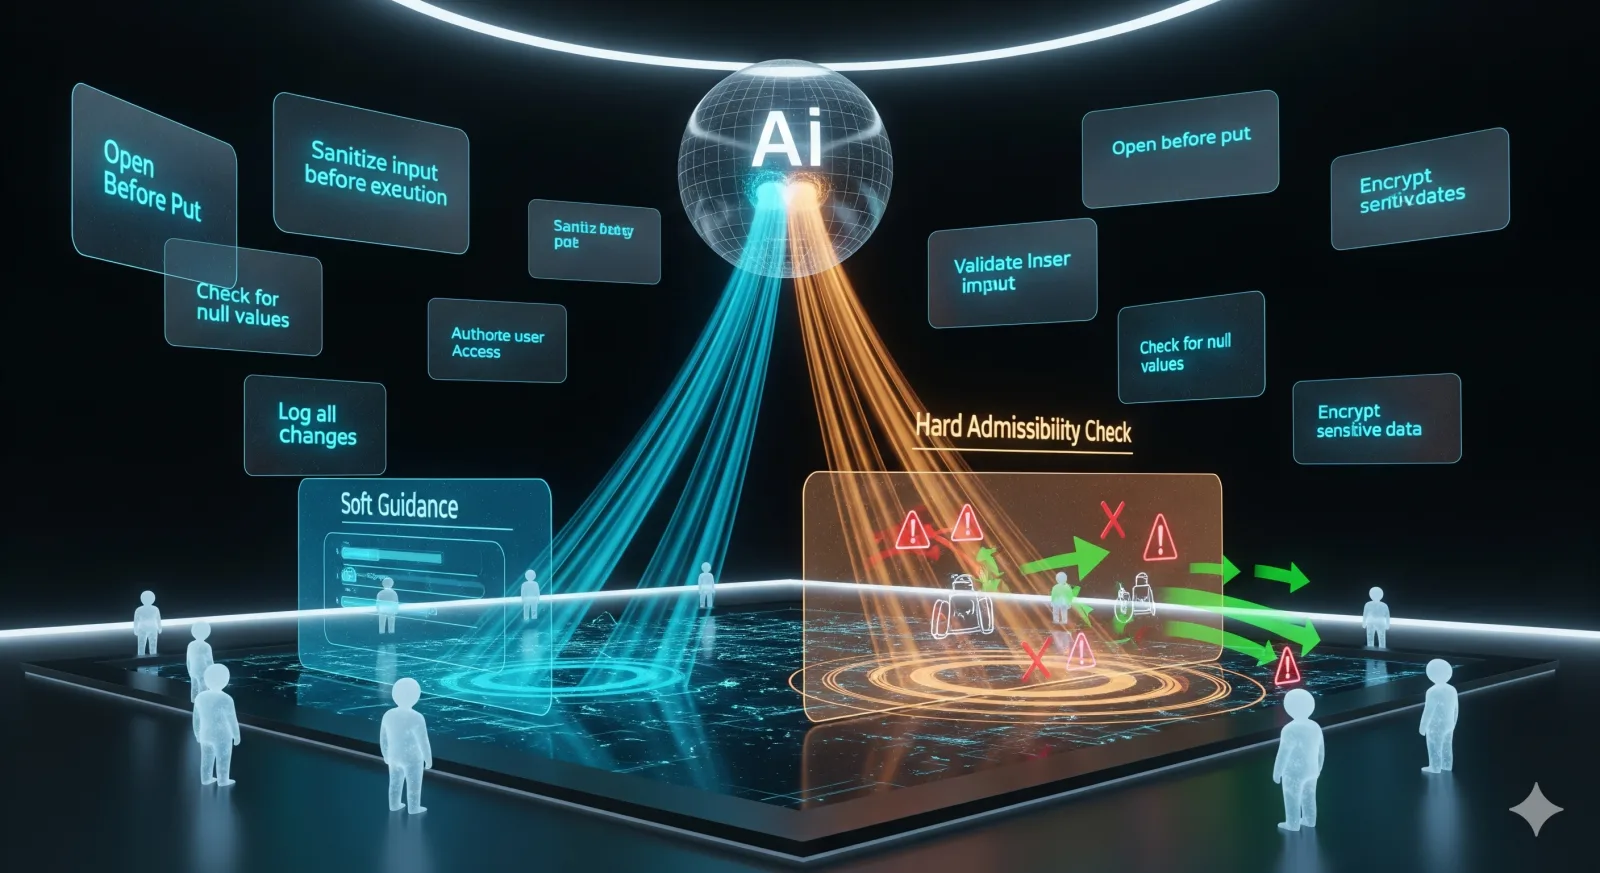
A support bot forgets the same refund exception every Monday. A procurement agent keeps calling the wrong API before checking vendor status. A workflow assistant learns, apologises, retries, then makes the same mistake next quarter because the lesson lived only in the chat transcript. Very human. Also not especially useful. That is the practical problem behind Meta-Policy Reflexion, a paper that asks whether LLM agents can keep the benefit of verbal self-reflection without turning every failure into a one-off therapy session.1 The authors propose Meta-Policy Reflexion (MPR), a training-free framework that distils failed-trajectory reflections into a structured Meta-Policy Memory (MPM), then uses that memory in two ways: softly, by putting relevant rules into the agent’s prompt; and hard, by checking generated actions against admissibility constraints before execution. ...

September 8, 2025 · 14 min · Zelina