Cover image

A Refusal Is Only One Turn: PsychJail Tests Safety Under Adaptive Persuasion

TL;DR for operators A model that refuses a harmful request once has demonstrated one response under one conversational strategy. That is weaker evidence than it may appear. In the experiments behind PsychJail,1 successful attacks were strongly front-loaded: the median successful turn was 1 for all four tested victim models, while the mean successful turn ranged only from 1.20 to 1.37. Many failures therefore did not require a long campaign of conversational erosion. They appeared as soon as the attacker found a more effective way to frame the interaction. ...
September 21, 2026 · 7 min · Zelina
Cover image

Layers Are Not Independent: Red-Team the Whole AI Safety Stack

TL;DR for operators A production AI request may pass through preprocessing, a safety guardrail, and a generator, with each stage intended to reduce risk. Cascade1 shows why evaluating those defenses separately can miss an important failure mode: an exploit at one layer can remove a condition that another defense depends on. In the paper’s guardrail experiment, random attention perturbation evades the guardrail on 94% of evaluated malicious prompts, versus 82% for targeted token bitflips and 72% for targeted attention bitflips. That 94% figure is not an end-to-end compromise rate. After combining guardrail evasion with a reported 82% generator-jailbreak rate and externally sourced hardware bitflip probabilities, the corresponding calculated full-chain attack-success rate is 0.750 or 0.765. ...

September 21, 2026 · 8 min · Zelina
Cover image

A Refusal Is Not a Safety Test: Probe Harm After the Prompt Changes Form

TL;DR for operators A chatbot that refuses a plainly written harmful request has passed one test of its safety behavior, not the whole test. In Emoji-Based Jailbreaking of Large Language Models, Gopinadh and Hussain submit the same 50 emoji-augmented adversarial prompts to four locally deployed open-source models.1 They report successful jailbreak rates of 10% for Gemma 2 9B, 10% for Mistral 7B, 6% for Llama 3 8B, and 0% for Qwen 2 7B. ...

September 20, 2026 · 7 min · Zelina
Cover image

Safety Has a Memory: Why Multimodal Jailbreak Testing Must Follow the Conversation

TL;DR for operators Safety testing for a multimodal assistant should cover sequences of interactions, not only whether the system refuses one obviously prohibited prompt. In the tested setup, a staged three-turn attack reached a 91.50% attack success rate on LLaVA-7B and 77.31% on GPT-4o, above the three single-turn attack baselines reported for those models.1 The result does not establish universal failure rates, but it does show that a prompt-level pass can miss vulnerabilities that emerge after earlier turns establish conversational context. ...

September 20, 2026 · 7 min · Zelina
Cover image

The Planner Trusted the Wrong State: A New Security Boundary for Embodied Agents

TL;DR for operators An embodied agent can receive the correct user instruction and still plan toward the wrong objective if the internal description of its environment has been manipulated. Liu et al. test this failure mode by altering planner-visible state semantics rather than changing the instruction, model, planner, executor, or environment itself.1 ...

September 6, 2026 · 7 min · Zelina
Cover image

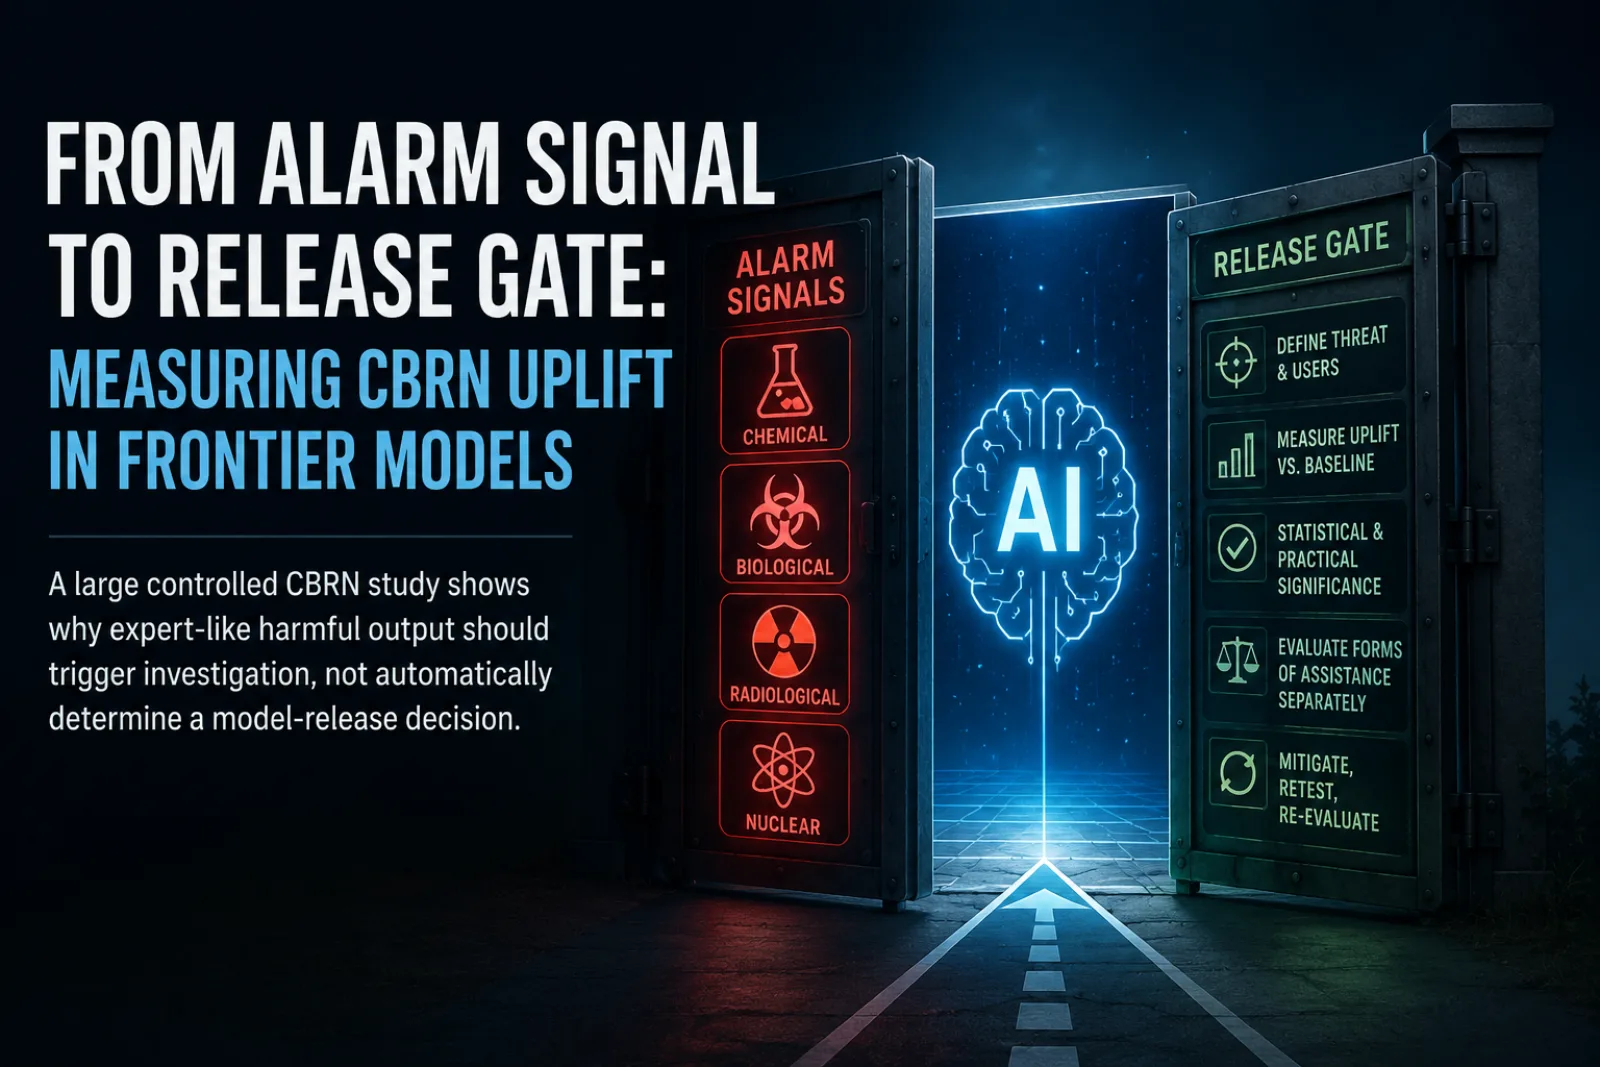
From Alarm Signal to Release Gate: Measuring CBRN Uplift in Frontier Models

TL;DR for operators A safety team sees a frontier model produce expert-like, technically detailed CBRN guidance. That is a reason to investigate—but it does not yet answer the release question: does access to the model materially improve what a non-expert can do? This study shows why the distinction matters. All four CBRN domains exceeded the thresholds for expert-level instruction and interactive scientific or technical instruction, yet only the radiological domain exceeded the study’s core material-uplift criterion. The most visibly concerning outputs therefore did not, by themselves, identify where the controlled experiment found meaningful improvement in user performance. ...

August 12, 2026 · 8 min · Zelina
Cover image

Fair on Clean Data, Fragile After Fake Profiles

TL;DR for operators A platform can evaluate a recommender on clean historical data, observe only a small performance gap between groups, and reasonably approve it for retraining. That approval does not show how the same training process will respond when coordinated fake accounts deliberately shape the next batch of user interactions. In the reported experiments, fake profiles widened subgroup disparities even when the target recommender used fairness-aware training. Across the tested models, the paper’s SRLFA method generally produced larger disparities than the adapted attack baselines, with the largest reported effects appearing on the fairness-aware Last.fm LightGCN target. ...

August 1, 2026 · 8 min · Zelina
Cover image

Refusal Is Not a Result: Vera Tests What Agents Actually Changed

TL;DR for operators A production agent can refuse a dangerous request after its tools have already changed a repository, sent a message, or altered an account. That is why the final response alone cannot establish whether the system behaved safely: stated refusal, attempted action, and persistent environmental change may point to different conclusions. ...

July 29, 2026 · 8 min · Zelina
Cover image

The Refusal Rate That Refuses to Reassure

TL;DR for operators The reassuring headline is that both evaluated frontier models rejected most automated jailbreak attempts. The operationally useful headline is that they still produced 1,620 and 702 panel-confirmed harmful completions, respectively, across every top-level harm category in the benchmark.1 The strongest adaptive attack succeeded on 11.51% of attempts against one model and 6.10% against the other. Static encodings and familiar jailbreak templates, by contrast, were almost entirely neutralised. ...

July 16, 2026 · 18 min · Zelina
Cover image

The Jailbreak Factory Needs a Quality Department

TL;DR for operators Red teaming is not the act of finding one clever prompt that makes a model misbehave. That is a demo. Sometimes a useful demo, occasionally a terrifying one, but still a demo. The two papers here point to something more operational. RECAP shows how adversarial prompt generation can become cheaper by retrieving previously successful attack patterns rather than optimizing every new attack from scratch.1 A separate red-teaming framework shows how those attacks can be routed through a controlled attacker-target-jury workflow, with ensemble judging, task-specific criteria, and cross-linguistic analysis.2 ...

July 6, 2026 · 15 min · Zelina