Cover image

Write the Memory Before You Search It

TL;DR for operators A long-running assistant can store the right fact and still fail to retrieve it because that fact was represented alongside several unrelated meanings. AutoViewMem1 addresses this before search begins: it learns complementary ways to interpret a user’s history, writes structured memories under those views, removes redundancy, and then uses ordinary top-K vector retrieval. ...

October 19, 2026 · 8 min · Zelina
Cover image

Self-Evolution Needs an Admission Gate

TL;DR for operators An agent that learns from previous cases can improve future decisions, but reuse also creates a new failure channel: a mistaken lesson can travel across cases. In the paper’s memory ablation, unverified memory updates produce 46.4% positive transfer but also 5.7% negative transfer. Adding verification and conflict retention cuts negative transfer to 0.2% while preserving 43.0% positive transfer and reaching 91.88% accuracy. ...

October 15, 2026 · 7 min · Zelina
Cover image

More Agents, More Rules: HiMA-MDD Treats Multi-Agent AI as a Governance Problem

TL;DR for operators Dividing a high-stakes decision among specialist agents does not specify who may see which evidence, who owns each subdecision, or who can revise it. HiMA-MDD1 turns those choices into explicit system rules for PHQ-8 assessment from completed multimodal clinical interviews. The strongest architectural signal is not “more agents perform better.” Before global verification, four specialists produce the lowest total-score error, while two specialists produce the highest screening kappa and Macro-F1. Removing cross-factor audit and targeted revision causes the largest screening-performance decline among the paper’s three component ablations. Giving four specialists bounded item-specific evidence also beats giving them a capped shared evidence pool on every reported pre-verification metric, although that experiment changes both evidence composition and context length. ...

September 25, 2026 · 6 min · Zelina
Cover image

Trust Signals Don’t Check Themselves: Put Verification Before the Install

TL;DR for operators If an AI coding assistant can install software, do not assume it will inspect the evidence already available about where that software came from. In Pengyin Shan’s pre-registered demand-side audit,1 only 9 of 1,920 registered trials retrieved a relevant trust signal before the install-or-decline decision. Across 2,114 completed registered and supplementary trials, not one assistant executed a signature or attestation verification command. ...

September 24, 2026 · 8 min · Zelina
Cover image

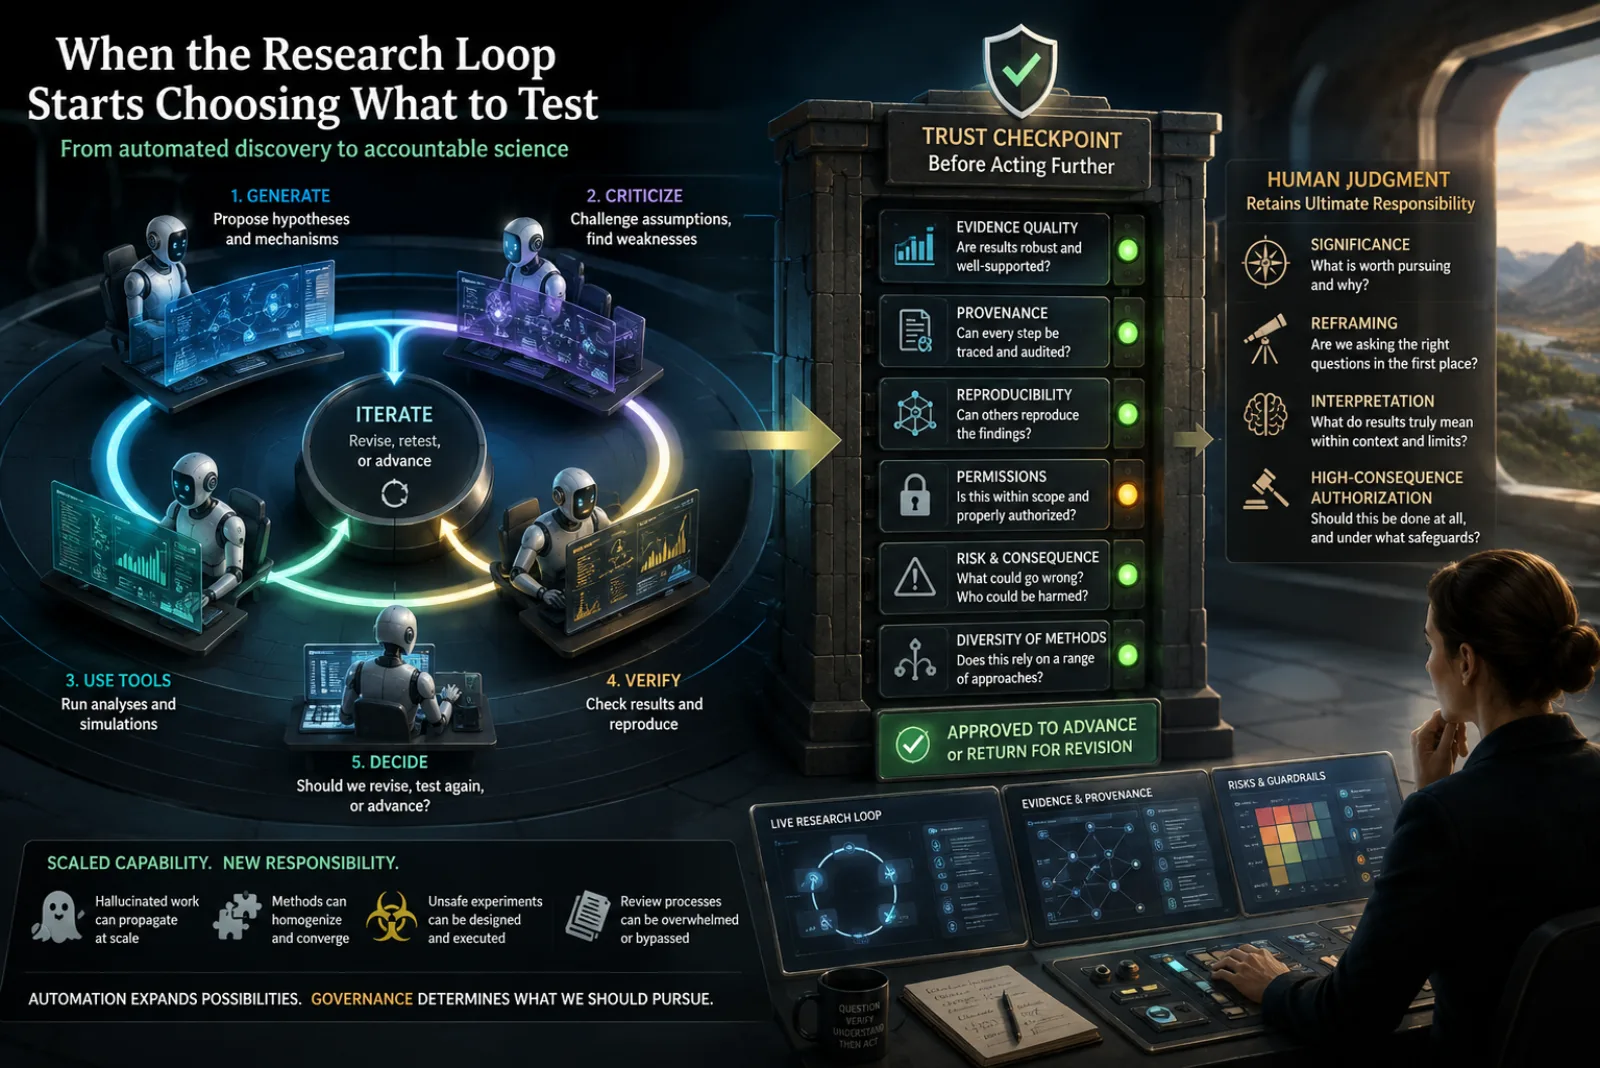
When the Research Loop Starts Choosing What to Test

TL;DR for operators A research assistant answers a question you give it. A more autonomous scientific system can propose a hypothesis, criticize it, run analyses, compare outcomes, and decide whether another iteration is warranted. Once these functions are coordinated, the operational unit is no longer a model call. It is a discovery loop. ...

September 2, 2026 · 7 min · Zelina
Cover image

Before the Agent Stores the Result

TL;DR for operators An analytical agent can select an appropriate tool, complete a computation, and return a plausible result while still being wrong at the point that matters operationally: deciding whether the result should be trusted, reported, stored, or used to launch further automated work. Brain Researcher addresses that later decision by making the research episode—not the model response—the governed unit of work. It constrains available resources, records provenance, tests alternative defensible specifications, assigns explicit states to scientific claims, and controls which results are eligible to enter memory. The paper reports a large improvement in first-action tool routing, from 23.3% without the system to 93.6% with it. Yet verified evidence grounding reaches only 22.0%, and an automated scientific-review layer still missed a scoring error that required human detection. ...
September 1, 2026 · 8 min · Zelina
Cover image

When 29 Scientific Records Become 7 Without Losing the Science

TL;DR for operators The paper addresses a problem that appears after literature retrieval succeeds. A research organization may already have the relevant papers and may even have extracted the reported measurements, yet those observations can still be unsafe to combine because material names, property definitions, units, temperatures, methods, and other conditions do not align. ...

September 1, 2026 · 7 min · Zelina
Cover image

The Best Query Is the One the User Never Knew to Ask

TL;DR for operators A retrieval system can answer only the questions a user thinks to ask. That becomes a design constraint when the user’s main problem is not missing information but missing awareness that information is missing. VeriForge addresses this by giving AI initiative over discovery while leaving the writer in control of synthesis. In a study of 12 writers, blind-spot alerting averaged 6.33 with VeriForge versus 3.00 with a strengthened baseline, and 11 of 12 participants rated VeriForge higher. Creativity support, exploration behavior, and expert-rated perceived domain competence also improved after statistical correction.1 ...

August 27, 2026 · 7 min · Zelina
Cover image

After the Bad Memory: Repairing the Decisions It Already Touched

TL;DR for operators When an agent discovers that a stored customer preference, prior observation, or workflow fact was wrong, deleting that record may be too late. The faulty information may already have shaped a plan, triggered a tool call, entered the final answer, or created new persistent memories. Yu et al. propose a repair mechanism that follows those dependencies rather than resetting everything.1 On their 150-case controlled benchmark, it recovered 85.3% of cases, compared with 77.3% for LLM-judge repair, while reducing the replay ratio from 21.7% to 12.3% and average LLM calls from 9.80 to 5.70. ...

August 21, 2026 · 7 min · Zelina
Cover image

Let the Model Design the Poster—Not the Evidence

TL;DR for operators A scientific poster can look polished and still fabricate the plots or diagrams readers interpret as evidence. PosterHarness separates those responsibilities: the image model designs the layout and decides where evidence should appear, but it must leave those regions blank for source-paper figures to be inserted later by deterministic code. ...

August 3, 2026 · 8 min · Zelina