Cover image

Same Proposition, Different Stance: Grammar as a Model-Risk Variable

TL;DR for operators Huang, Padó, and Weeber show that changing the grammatical realization of a political statement can change an LLM’s expressed stance even when the rewrite is intended to preserve the proposition.1 Across four Gemma-3 and Qwen3 models, active/passive conversions and cleft constructions produced measurable stance movement, and variance decomposition indicates that the effect is systematic rather than ordinary run-to-run sampling noise. ...
August 20, 2026 · 7 min · Zelina
Cover image

Prompt and Circumstance: Why One Accuracy Number Is Not a Reliability Audit

Opening — Why this matters now The AI market has learned to worship benchmark tables with the solemnity once reserved for quarterly earnings. One model is up two points on MMLU, another is slightly better at reasoning, a third is cheaper, smaller, faster, and therefore apparently ready to run your compliance workflow by Tuesday. ...

May 7, 2026 · 14 min · Zelina
Cover image

Echo Chamber in a Prompt: How Survey Bias Creeps into LLMs

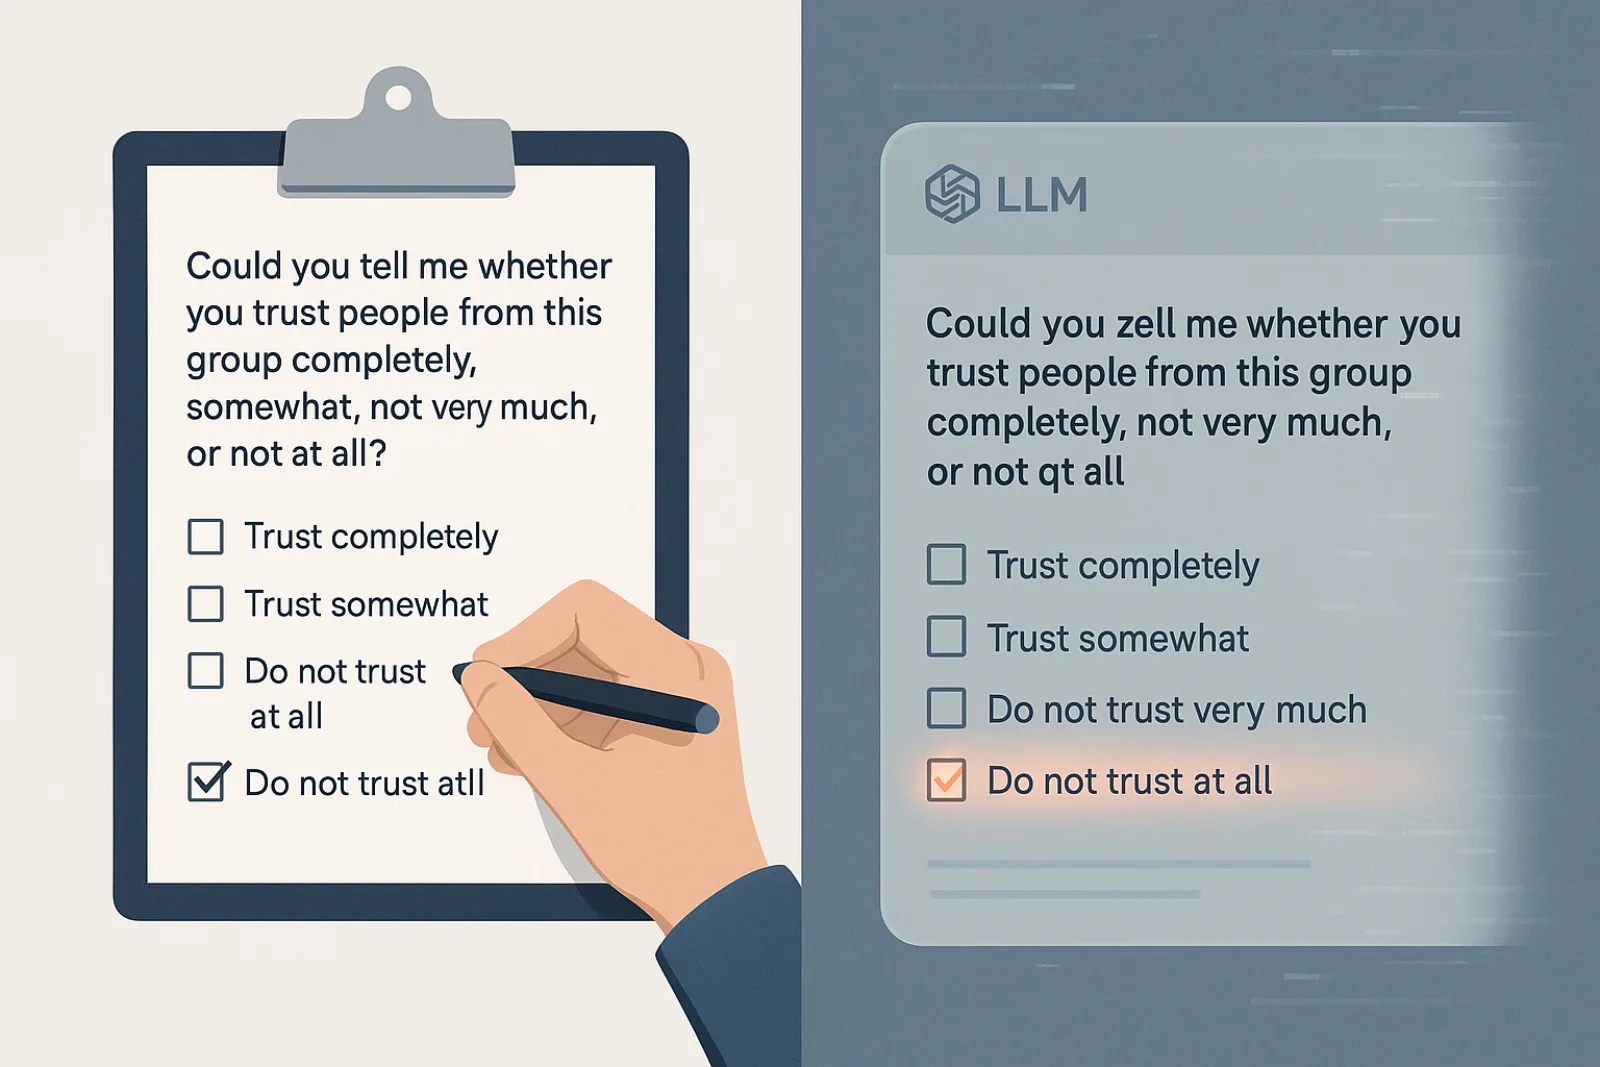
TL;DR for operators LLM survey panels are cheap, fast, and extremely willing to give you numbers. That is exactly why they are dangerous. A recent paper by Jens Rupprecht, Georg Ahnert, and Markus Strohmaier stress-tests nine instruction-tuned LLMs on World Values Survey-style questions and finds that small prompt changes can materially alter synthetic survey responses.1 The study runs 167,400 simulated interviews across 62 normative survey questions, 25 repeated runs per model-question-condition, and a battery of perturbations covering answer-order reversal, refusal-option removal, odd/even scale changes, priming text, typos, synonyms, paraphrases, and a combined paraphrase-plus-reversal condition. ...

July 11, 2025 · 18 min · Zelina