Cover image

Choose the Bottleneck Before the KV Cache Strategy

TL;DR for operators Mamo, Kogiou, Yi, and Yu compare three representative approaches to managing the memory accumulated during LLM generation: keep the full cache on the GPU, permanently discard selected cached tokens, or retain the larger cache in CPU memory and fetch selected entries during decoding.1 Their benchmark finds no dominant strategy. ...
September 4, 2026 · 7 min · Zelina
Cover image

Not Every Layer Deserves the Same Cache

TL;DR for operators A compressed KV cache creates two separate decisions: which tokens to retain inside each Transformer layer, and how much of the total cache budget each layer should receive. The second decision is easy to hide behind uniform allocations or simple depth schedules, but the evidence here suggests that those rules can spend scarce GPU memory in the wrong places. ...

September 1, 2026 · 7 min · Zelina
Cover image

Packing Memory, Not Problems: How Short Clips Teach AI to Think Long in Video

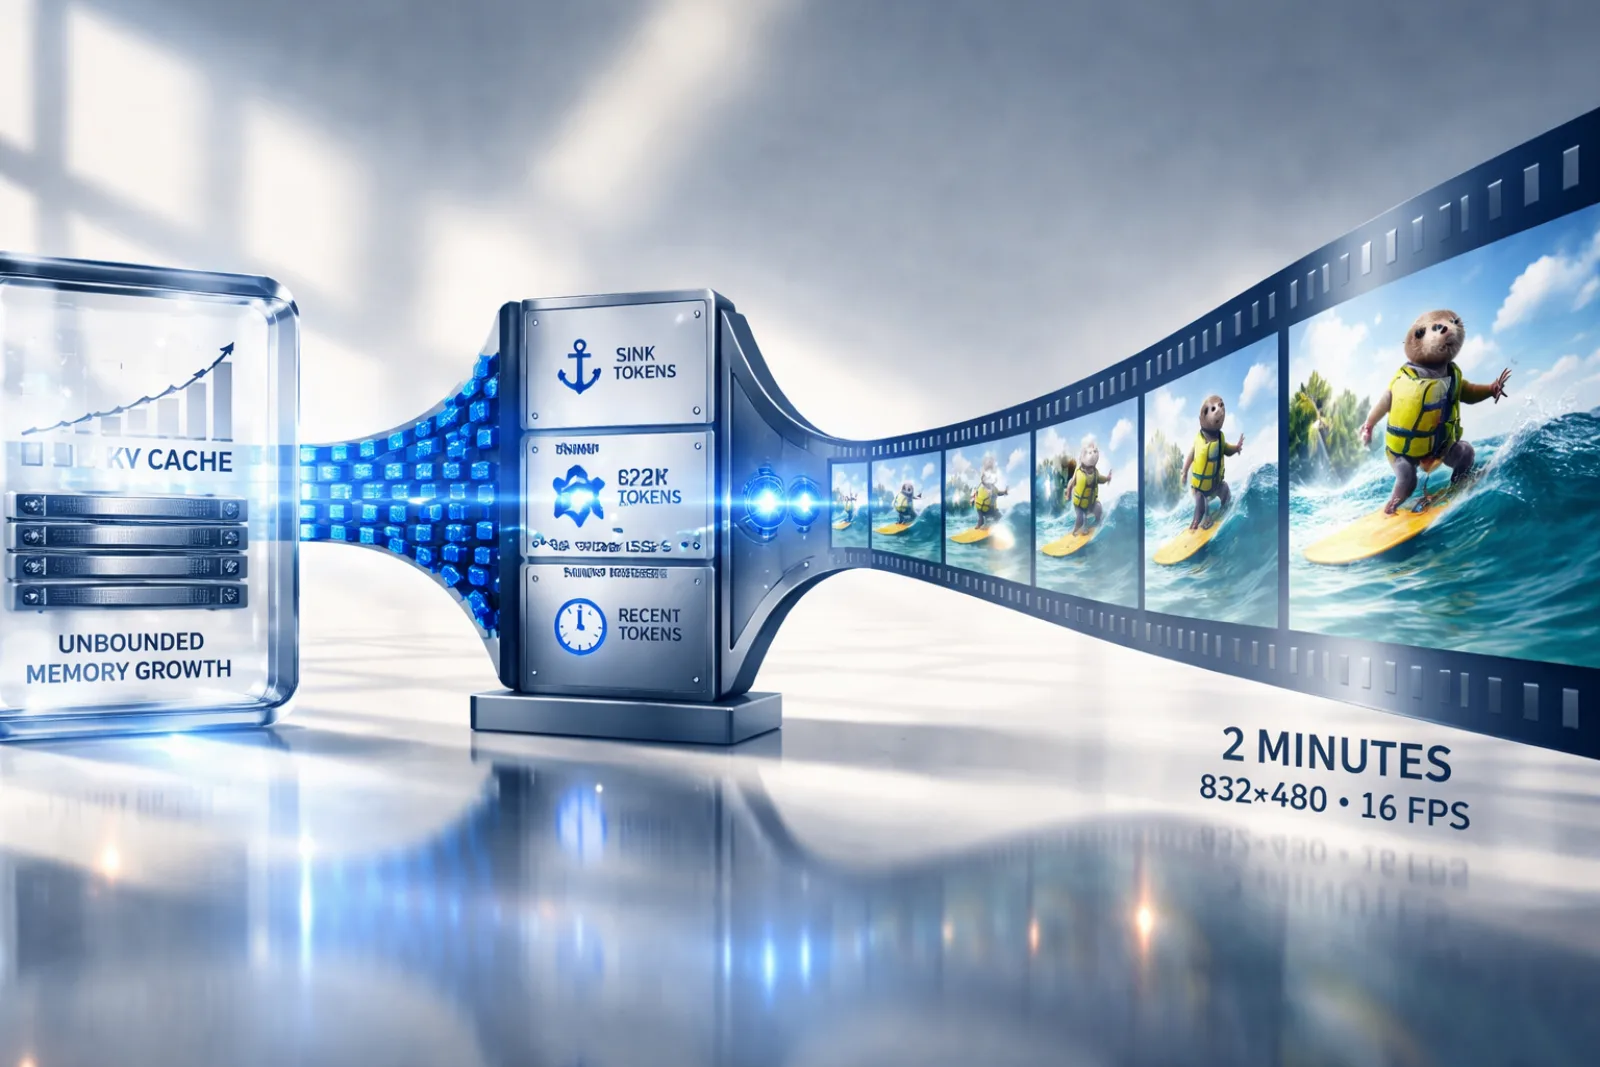
Memory is usually the boring part of AI demos. The model gets the spotlight. The prompt gets the applause. The generated video either looks magical or embarrassingly haunted. Somewhere underneath, quietly paying the bill, sits the memory system. It decides what the model can still remember, what it must forget, and how much GPU memory gets sacrificed to the gods of temporal coherence. ...

March 28, 2026 · 20 min · Zelina