The Right Answer Is Not a Proof: Put Verification Inside the Reasoning Loop
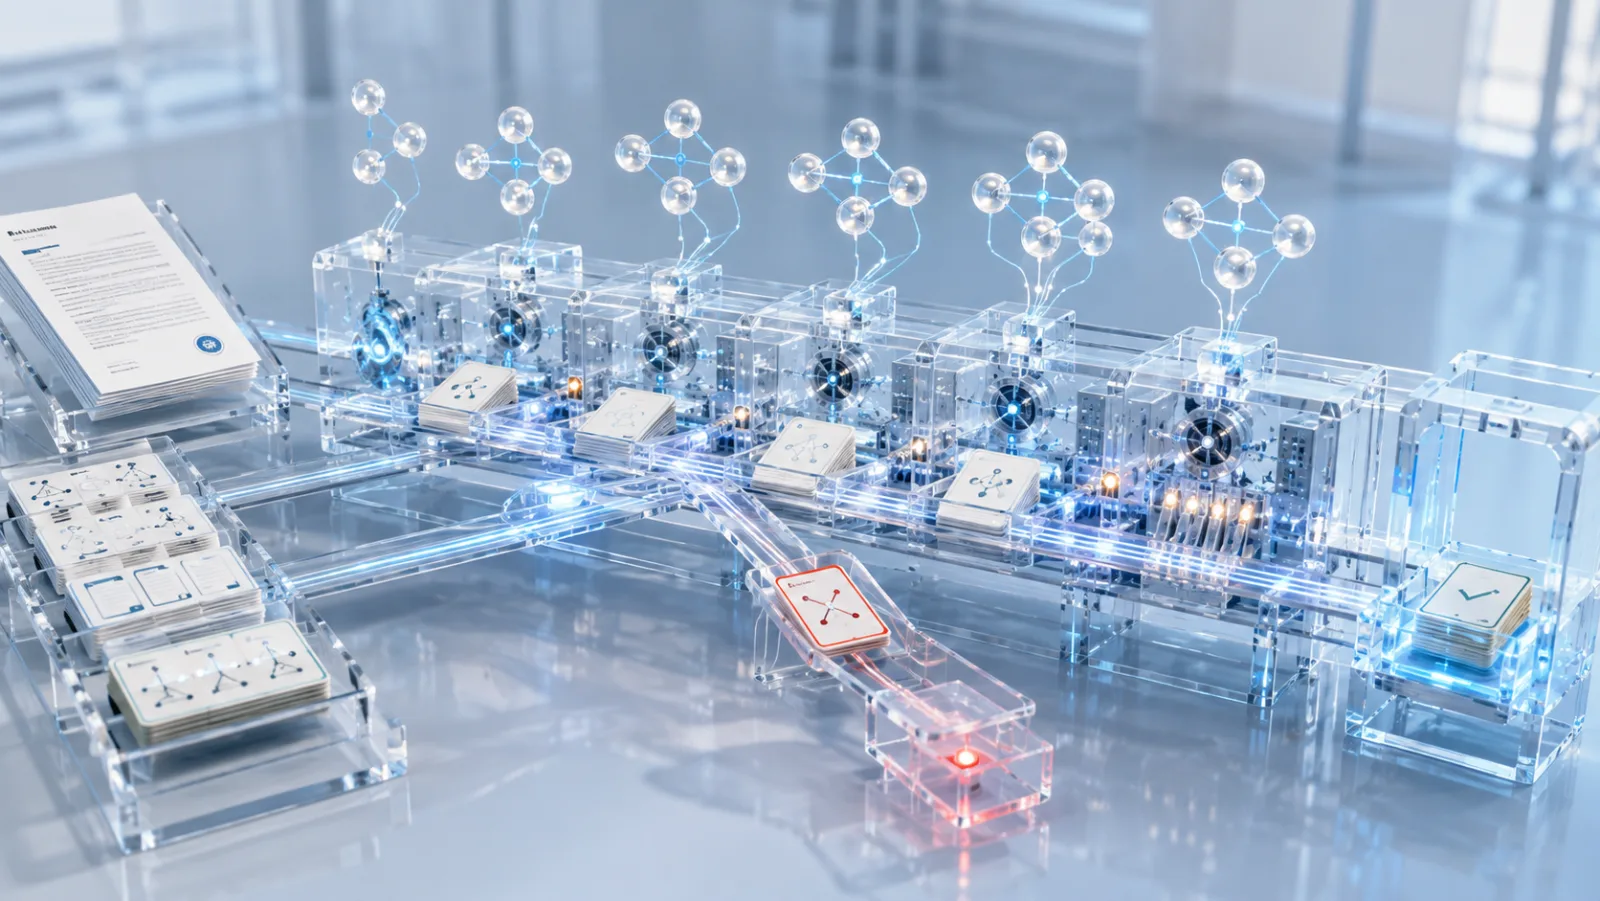
TL;DR for operators A model can produce a correct answer while taking a logically invalid route to get there. That distinction matters whenever downstream execution depends not only on the answer, but on whether the intermediate decisions are trustworthy. Chen, Zhou, and Zhang test a lighter alternative to full theorem-proof generation: PRoSFI, which asks a 7B model to expose small, machine-readable reasoning steps that external formal tools can verify.1 On ProverQA-Hard, outcome-only reinforcement learning reaches 91.31% answer accuracy but only 21.97% GPT Soundness. PRoSFI reaches 92.97% accuracy and 76.07% GPT Soundness. The practical lesson is not that every business workflow should be formalized. It is that when intermediate decisions can be expressed as checkable rules, adding a verification layer can provide a stronger reliability signal than final-answer accuracy alone. ...