Cover image

Train Where the Retriever Is Confused

TL;DR for operators REPAIR suggests that the next improvement to a specialized retriever does not necessarily require a larger model or a much larger synthetic dataset. The paper instead concentrates training effort on queries where the current retriever has difficulty separating a known positive from its strongest competitor, identifies the concepts associated with those failures, and generates new supervision only after grounding it in external scientific evidence. ...
October 15, 2026 · 7 min · Zelina
Cover image

Divide & Verify: When Decomposition Finally Learns to Behave

A report is only as trustworthy as the sentence nobody checked. That sounds melodramatic until an LLM-generated due diligence note, policy memo, customer support answer, or compliance summary contains three correct facts and one quiet falsehood in the same paragraph. The usual fix is simple in theory: split the answer into smaller claims, retrieve evidence for each claim, let a verifier judge them, and aggregate the results. ...

February 26, 2026 · 17 min · Zelina
Cover image

Fusion Cuisine for RAG: Z‑Scores, Rankers, and the Two‑Source Diet

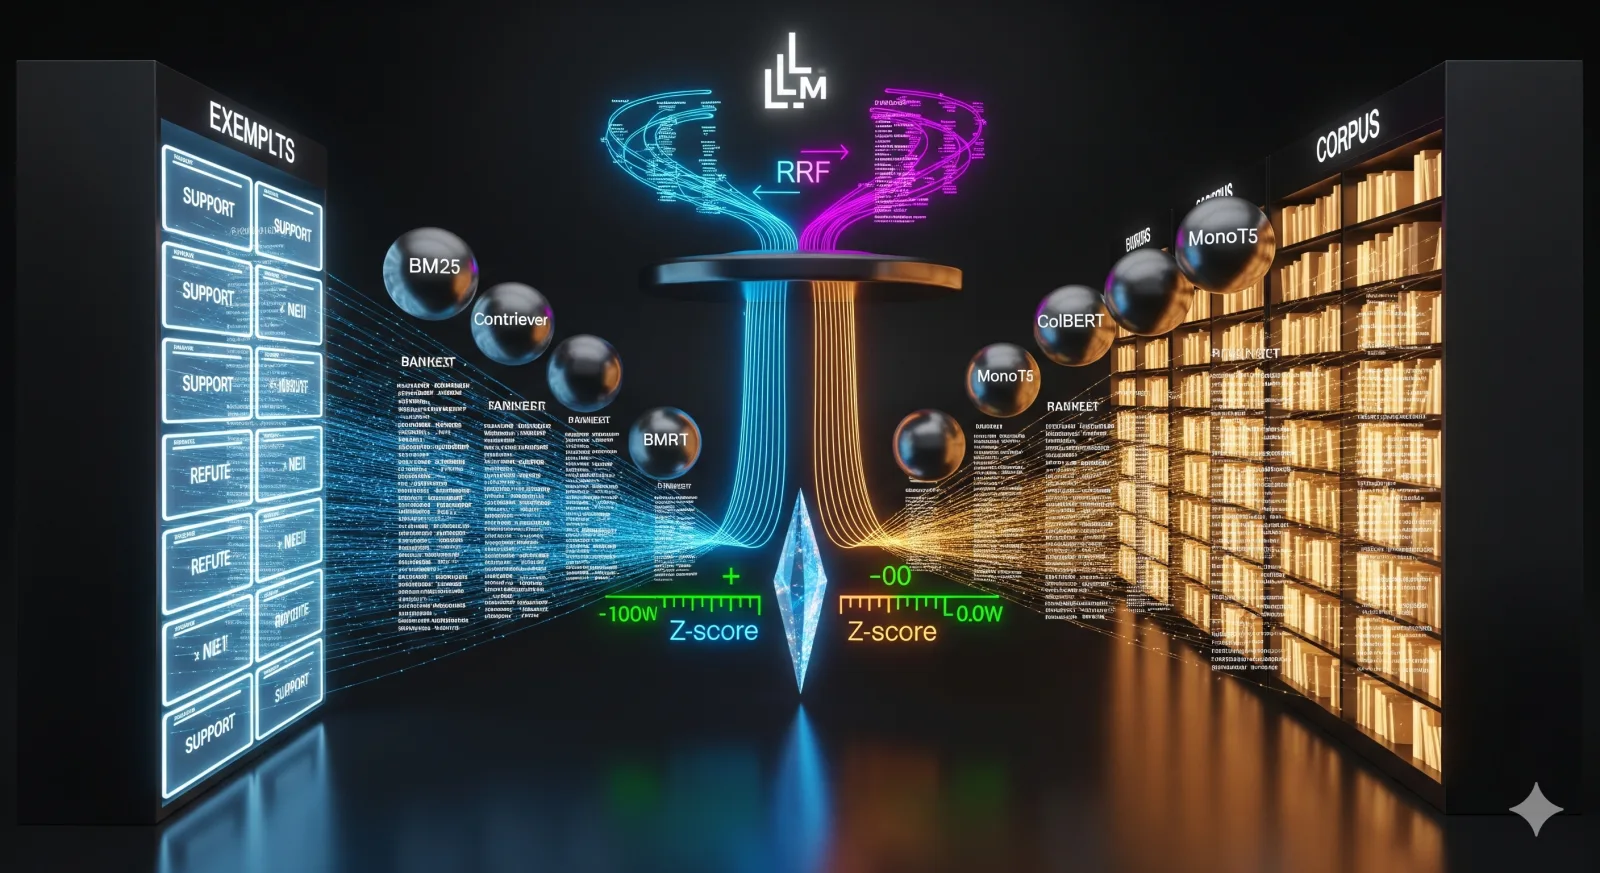
A RAG system usually fails in one of two annoyingly familiar ways. It retrieves documents that are factually relevant but gives the model no clue about the task’s decision boundary. Or it retrieves labelled examples that show the decision pattern but are too parochial to help when the topic drifts. One source knows the world. The other knows the exam rubric. Naturally, many systems pick one and then pretend the compromise was strategy. ...

September 6, 2025 · 15 min · Zelina