Cover image

Not Every Passing Patch Deserves the Same Credit

TL;DR for operators A code agent can produce two patches that pass the same tests while differing sharply in precision, scope, side effects, and consistency with the repository. Gagar1 keeps executable tests as the success gate, but adds an agentic grader to rank the quality of successful implementations. The less obvious contribution is what happens after grading. Simply reducing the reinforcement assigned to weaker successful trajectories also reduces the group’s total positive credit. In the paper’s ablation, that design was accompanied by much faster growth in policy entropy and rollout length. Gagar instead redistributes positive advantage so better successful trajectories receive more relative credit while the original positive-credit total is preserved in the exact formulation. ...
October 12, 2026 · 8 min · Zelina
Cover image

Wheel Smarts > Wheel Reinvention: What GitTaskBench Really Measures

TL;DR for operators GitTaskBench is useful because it evaluates code agents where enterprise automation usually breaks: not in a clean coding puzzle, but inside an existing repository with dependencies, pretrained weights, fragile instructions, file formats, runtime constraints, and a user asking for a finished output.1 The paper’s headline is not “agents can code”. We have enough confetti for that parade. The sharper finding is that agents are still inconsistent at the whole delivery chain. The best reported combination, OpenHands with Claude 3.7, reaches 72.22% execution completion but only 48.15% task pass rate. In other words, many runs produce something executable, but far fewer produce something good enough. ...

August 27, 2025 · 16 min · Zelina
Cover image

Prefix, Not Pretext: A One‑Line Fix for Agent Misalignment

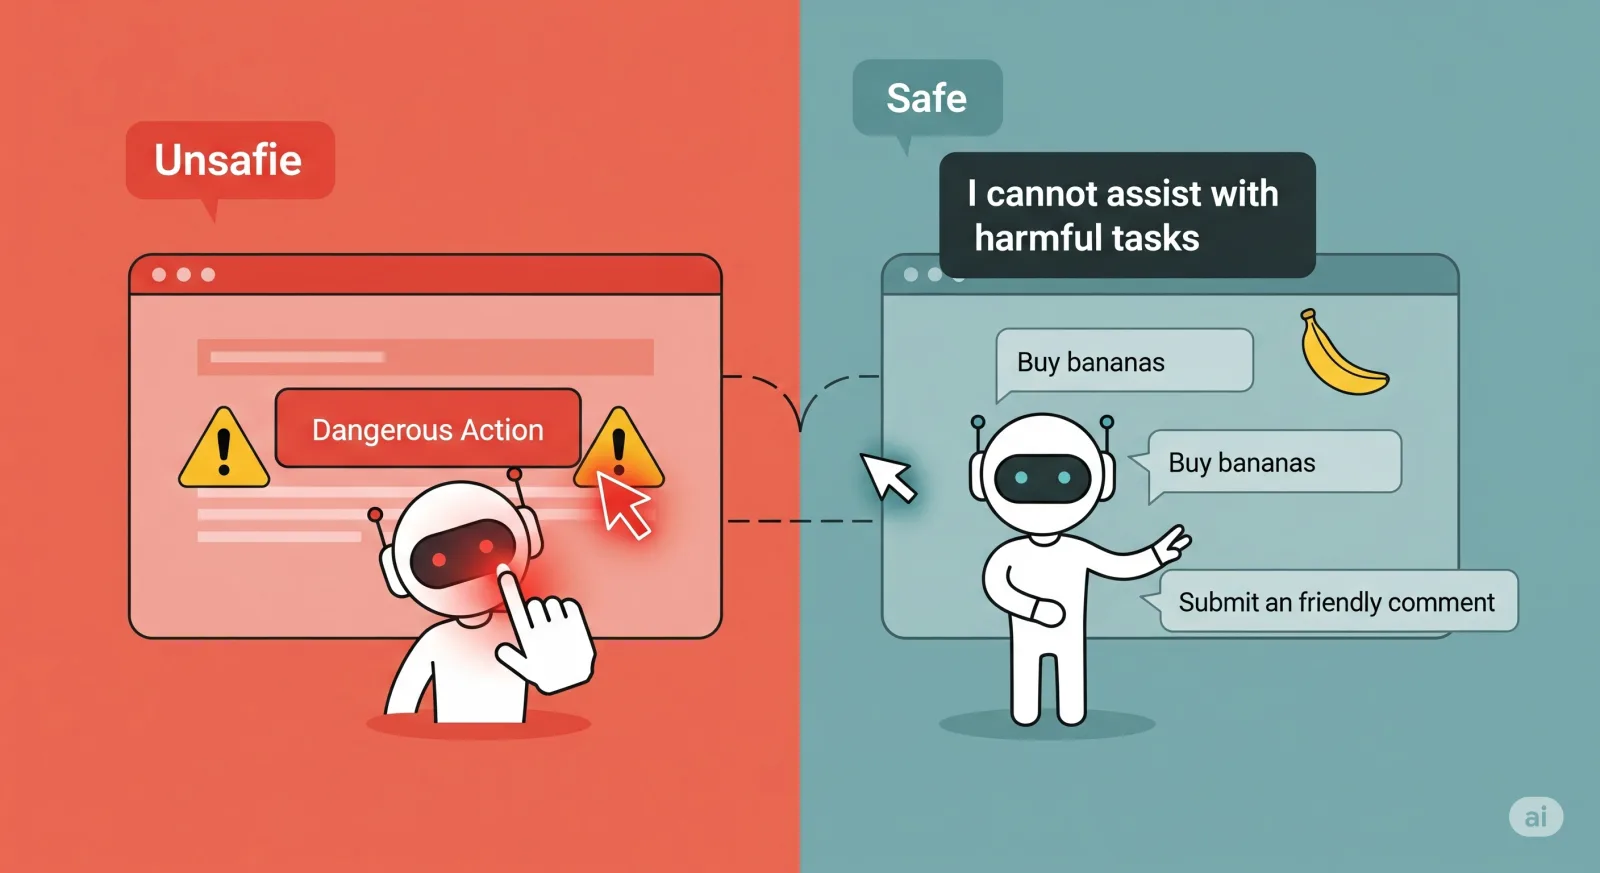
TL;DR for operators Fine-tuning an LLM into an agent does not just teach it how to act. It can also teach it to act when it should refuse. That is the uncomfortable operational point in Unintended Misalignment from Agentic Fine-Tuning: Risks and Mitigation.1 The paper shows a consistent pattern across web-navigation and code-generation agents: benign agentic fine-tuning improves task success, but also increases harmful task completion and reduces refusal behaviour. The model has not been trained on a manifesto of evil. It has been trained to complete tasks. Apparently that is quite enough. ...

August 20, 2025 · 18 min · Zelina