Cover image

Train the Family, Not Every Size From Scratch

TL;DR for operators A team that needs small, medium, and large versions of the same foundation model would normally budget several substantial pre-training runs. That accounting assumes each model must relearn most of the family’s shared representation from scratch. Chain-of-Models Pre-Training (CoM-PT)1 challenges that assumption. The smallest model is trained normally; each larger model then inherits parameters and feature guidance from the immediately smaller predecessor. On CC3M, the paper’s four-model ViT family cuts accumulated training MACs from 16.70 to 2.94 in the reported units, equivalent to 5.68x accumulated acceleration. Its ViT-L/16 endpoint also exceeds the individually trained baseline on ImageNet-1K, VTAB+, and COCO. ...
September 12, 2026 · 8 min · Zelina
Cover image

One-Shot, No Drama: Why Training-Free Federated VLMs Might Actually Work

Deployment is where elegant AI systems go to discover invoices, weak networks, compliance teams, and client devices with the computing dignity of a hotel lobby printer. Federated vision–language models make that problem worse. In theory, they are attractive: keep local data local, let many clients collaborate, and adapt a powerful pre-trained model to distributed visual tasks. In practice, the standard recipe usually asks every client to participate in repeated training rounds, exchange updates, survive connectivity gaps, and somehow not turn the entire project into a GPU-themed charity event. ...

November 23, 2025 · 16 min · Zelina
Cover image

Fake News Feels Different: How SEER Uses Emotion and Semantics to Spot Deception

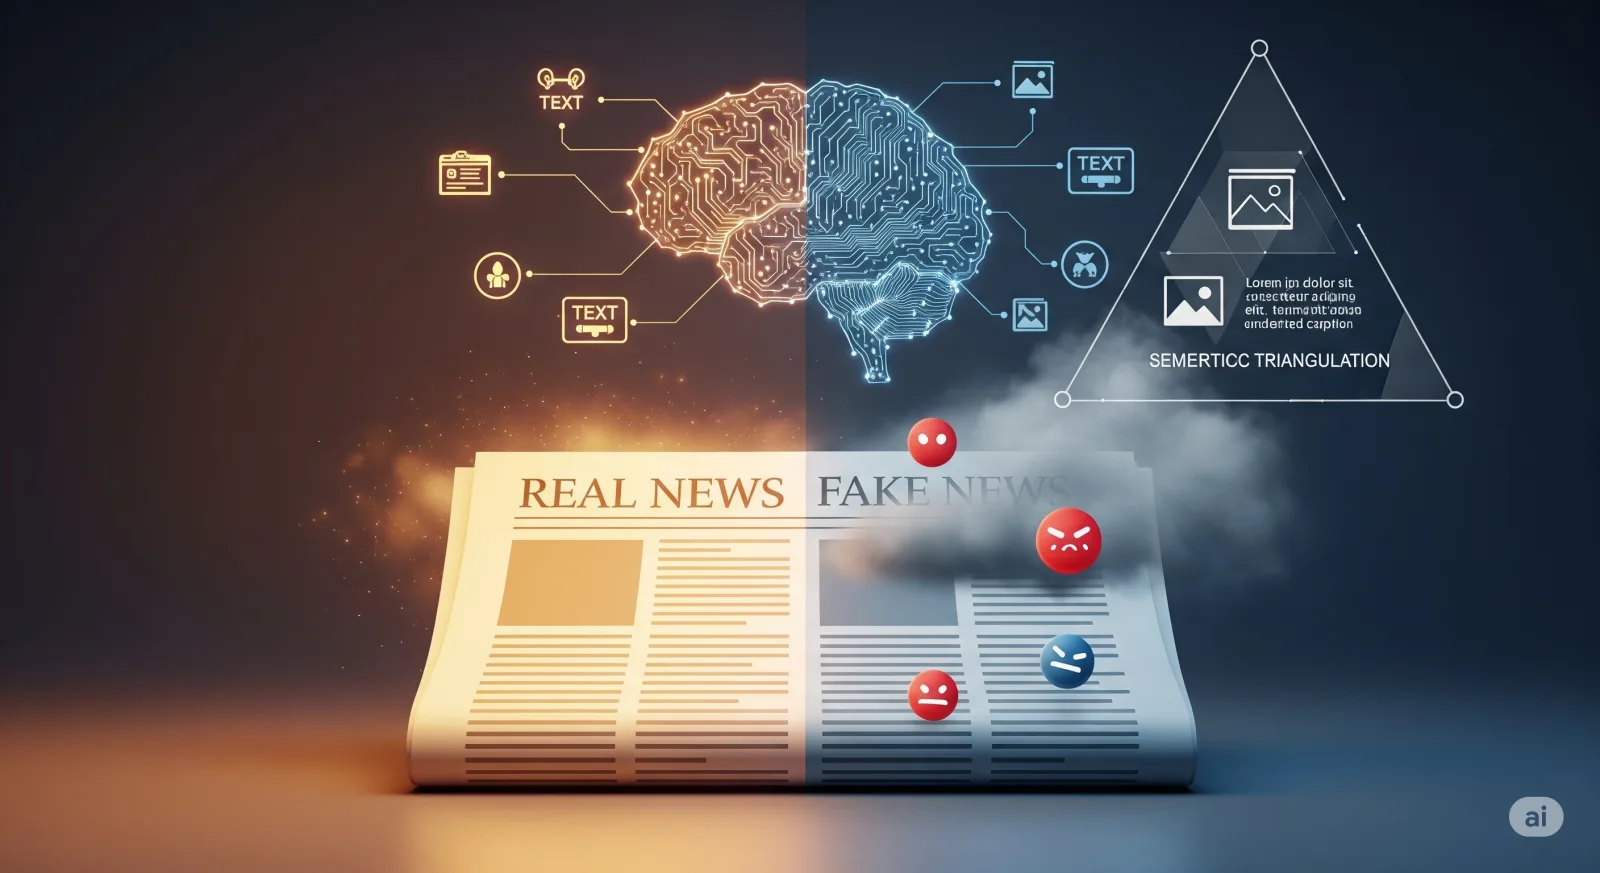
TL;DR for operators SEER is not a “sentiment detector for lies.” That would be wonderfully simple and operationally disastrous. It is a multimodal fake-news detection architecture that first tries to make images more semantically usable, then adds emotion as a probabilistic auxiliary signal rather than a moral verdict. The practical workflow is easy to understand: generate a caption for the image, align the text-image relationship using CLIP-style representations, fuse text, image, and caption features through attention, then use an expert emotional reasoning module to learn how emotional tone correlates with authenticity in the dataset. The paper reports accuracy of 0.929 on Weibo and 0.931 on Twitter, outperforming the tested baselines.1 ...

July 21, 2025 · 15 min · Zelina
Cover image

Prompt Without Words: Distilling GPT Semantics for Smarter Vision Models

TL;DR for operators Most attempts to improve CLIP-style image classification with large language models follow a familiar ritual: ask GPT to describe a class, paste those descriptions into prompts, then hope the model pays attention to the useful bits. The problem is that GPT’s descriptions are not stable objects. They vary by query wording, include hedged statements, and sometimes contain features that are hard or impossible to verify visually. “Usually,” “may,” and “often” are not exactly the foundations of a disciplined recognition system. ...

July 13, 2025 · 14 min · Zelina

CLIP ViT-B/32

A widely used multimodal model from OpenAI that learns joint image–text embeddings, enabling zero-shot image classification, search, and multimodal applications.

1 min