Where to Go Deeper Beyond This Academy
A curated guide to textbooks, authors, websites, and papers for readers who want to study transformer internals, attention math, fine-tuning, GPU optimization, and benchmarking in more depth.
A curated guide to textbooks, authors, websites, and papers for readers who want to study transformer internals, attention math, fine-tuning, GPU optimization, and benchmarking in more depth.
TL;DR for operators A household robot can put an object in the correct place while ignoring instructions about how to handle it. A dashboard reporting only task completion would count that operation as successful, even when the user explicitly requested a different handling method. LIBERO-PeRM makes that discrepancy measurable. In one zero-shot evaluation, a vision-language-action model completed 97.50% of motion-preference tasks, yet its preference-satisfaction score was only 24.38%. Skill-preference tasks showed a similar gap: 100.00% task success against 25.00% satisfaction. ...
TL;DR for operators A robot that opens a door has made a route accessible, but it has not necessarily found the object it was sent to retrieve. In a 3,000-episode simulated benchmark, an agent that maintains interaction-state memory and verifies physical changes achieves 41.63% terminal success, compared with 10.53% for an adapted baseline. Replacing execution-informed state updates with perception-only updates produces a particularly large performance decline in a smaller component test. ...
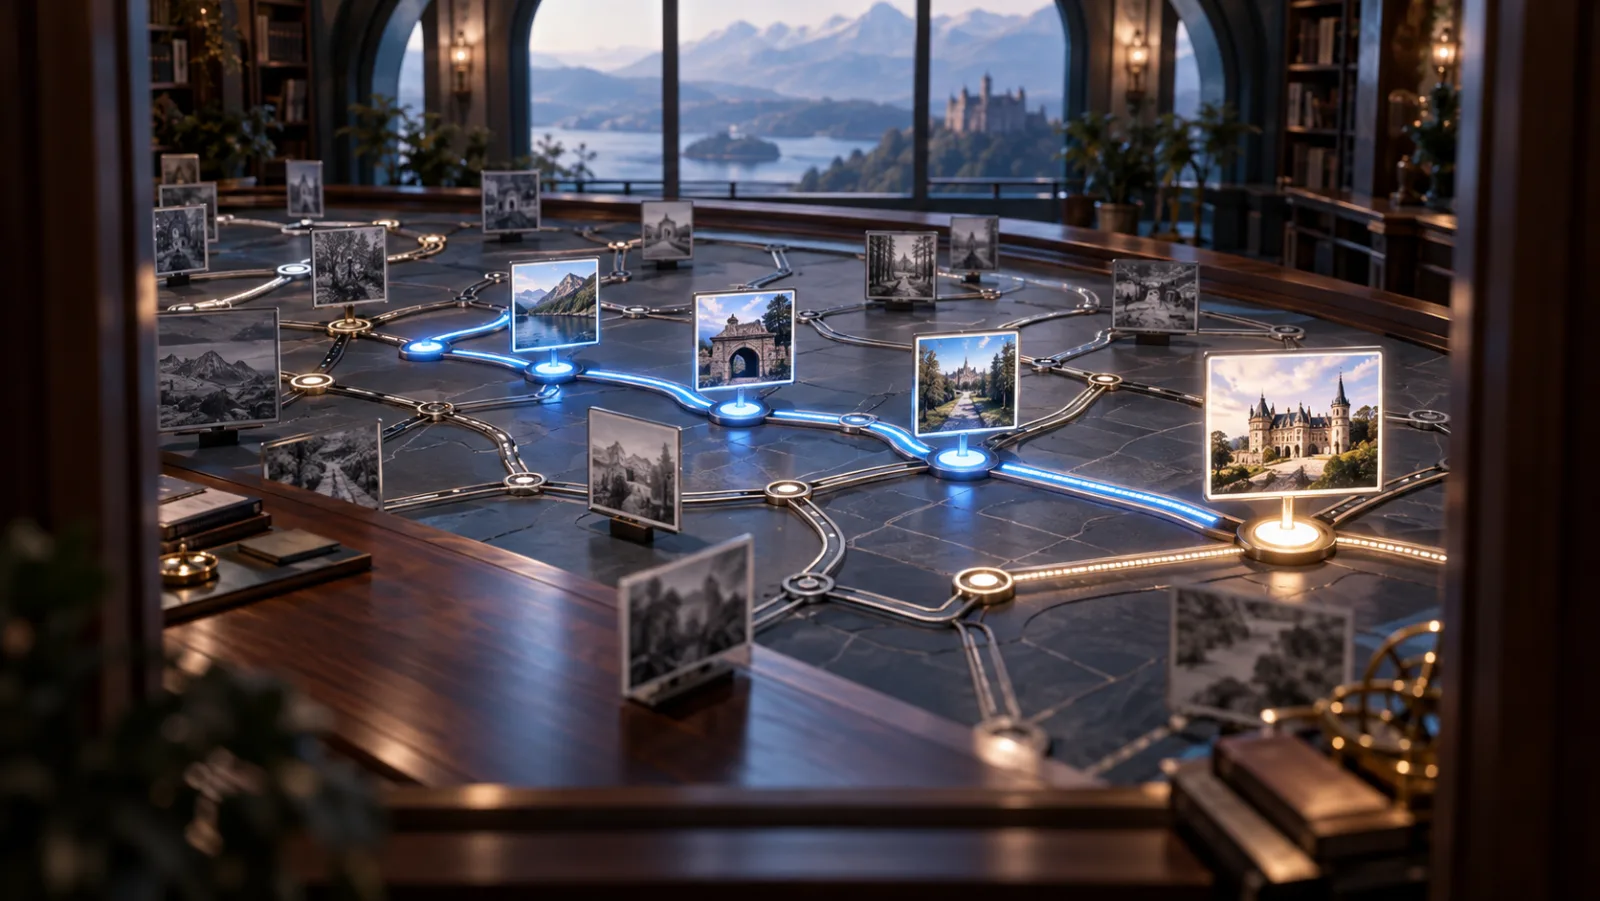
TL;DR for operators A multimodal agent may fail to find an image because the necessary evidence emerges only after several dependent searches. Upgrading its language model does not necessarily resolve that retrieval bottleneck. Chen, Zhou, and Wu’s VHop-Router1 moves sequential image selection, backtracking, and stopping into the retrieval tool itself. On 300 held-out three-hop visual-search questions, upgrading retrieval improves agent success from 32.7% to 85.4%, a 52.7-percentage-point gain. Upgrading the agent while retaining conventional retrieval produces only a small improvement. ...
TL;DR for operators When a stakeholder gives a coding agent a vague software request, asking clarification questions can improve the resulting specification. But asking effective questions and accurately documenting the answers are different capabilities. A benchmark covering 341 development tasks finds that the model with the highest proportion of effective clarification questions achieves substantially lower requirement alignment than the model with the lowest proportion. Coding-agent harnesses also improve question-level metrics while generally weakening specification quality. ...
TL;DR for operators An analytical workflow can be translated into code that executes successfully while silently changing its results. On ORCA-Main, Claude-Opus-4.6 achieves 75.07% success translating NumPy to Pandas but only 32.93% in the reverse direction—a 42.14-percentage-point gap. The ORCA benchmark1 evaluates this problem across 1,800 data science translation tasks. The asymmetry challenges the assumption that migration is primarily a matter of replacing equivalent API calls. Translation difficulty also depends on how source-library operations can be reconstructed in the target library. Complete workflows introduce another risk: individually correct transformations can still produce incompatible schemas, feature ordering, or preprocessing states. The leading model achieves 56.92% on the full ORCA-Main benchmark and 33.67% on ORCA-Project under a separate evaluation configuration; these scores are not a controlled comparison of project difficulty. ...
TL;DR for operators When several models all score near the top of an internal multiple-choice suite, the benchmark may still contain useful information. The remaining problem can be the evaluation format rather than the questions themselves. The paper introduces answer pooling: combine the answer options from several related questions, then require the model to assign one candidate to each question without reusing candidates. The questions and correct labels do not change. Across eight benchmarks and eighteen models, every evaluated model scores lower under pooling, and model rankings move enough that the format can affect comparative decisions. ...
TL;DR for operators Schug and Lake test a stricter question than whether a reasoning model can solve a problem: does the capability survive when the same latent problem is presented in an equivalent form?1 Across several controlled rule-induction tasks, the answer is often no. The most concrete example comes from integer-sequence program induction. Claude Opus 4.7 solves at least one tested variant in 91.67% of variation sets, but solves all five equivalent variants in only 50.00%. That 41.67 percentage-point gap means a model can look highly capable when evaluation rewards at least one successful formulation while remaining materially sensitive to harmless representational changes. ...
TL;DR for operators A materials team choosing a surrogate model for polymer screening should not treat molecular representation as a preprocessing detail. PolyBench261 compares language-model, graph-based, and descriptor-based approaches across 249,962 polymer-property datapoints, eight properties, four polymer architectures, and four evaluation tasks. Graph-based Polymer Chemprop (PC) and Polymer Periodic Graph (PPG) generally achieve the lowest errors on the evaluated in-distribution tasks. ...
TL;DR for operators A financial agent can retrieve the correct filing, extract a defensible figure, ask a relevant follow-up question—and still return the wrong answer for what the user meant. The clearest evidence is the gap between knowing the interpretation and having to recover it. When evaluated models are supplied with the disambiguating interpretation, their accuracy rises to roughly 90-95%. Under full free interaction, where the agent must decide what to clarify and use the answer correctly, the best result is 28.9%. ...