Cover image

Four Inputs In, One Modality Out: Testing Whether Omnimodal Models Actually Arbitrate Evidence

TL;DR for operators A model can receive a camera feed, spoken report, reference image, and text record without meaningfully reasoning across all four. In C$^3$PO1, 86–95% of observed failures across ten models in the paper’s failure analysis were classified as dominance-driven: one modality or prior drove the answer while other evidence was effectively ignored. ...

September 13, 2026 · 7 min · Zelina
Cover image

The Wrong Answer May Start Before Reasoning

TL;DR for operators A model reads a chart, diagram, or photographed math problem and produces the wrong answer. Treating that event as a generic “reasoning failure” can send engineering effort to the wrong component. The model may have misread a number, attached a label to the wrong object, confused a scale or unit, or reasoned incorrectly after extracting the right facts. ...

September 13, 2026 · 8 min · Zelina
Cover image

The Table Is the Task: What DataSpace Reveals About Data-Agent Reliability

TL;DR for operators A data agent can find the right evidence, perform much of the required analysis, and still fail the task by returning the wrong table. In an audit of 136 failed runs from the strongest tested backbone, 71 failures—52.2%—were attributed primarily to turning the agent’s internal result into the requested output. Sixty of those involved submitting extra or missing columns. Only three failures were attributed to selecting the wrong evidence source. ...

August 30, 2026 · 7 min · Zelina
Cover image

Running Is Not Correct: Why Scientific Code Needs Graded Verification

TL;DR for operators For generated engineering code, successful execution should be treated as a feasibility check, not a correctness certificate. In the paper’s 7B ablation, reinforcement learning based only on program validity reaches pass@1 of 0.58 and pass@8 of 0.76. Adding continuous trajectory accuracy raises those figures to 0.71 and 0.84. The mechanism is straightforward. Generated solver code must first run, return the required output shape, and avoid non-finite values. Programs that clear those checks are then graded by how closely their numerical trajectories match hidden references and, where available, how consistent their outputs are with the governing PDE. ...

August 14, 2026 · 8 min · Zelina
Cover image

Control in Degrees: Why Reliable AI Needs Calibrated Intervention

TL;DR for operators Reliability is often treated as a binary control problem: approve or reject an agent action, preserve or replace a learned component. The evidence here points to a second question that can matter just as much: how strongly should the system intervene, where, and under what conditions? The clearest technical example comes from continual reinforcement learning. In a 400-million-step SlipperyAnt stress test, CPR recorded zero policy collapses across all 15 seeds under the paper’s main collapse criterion, while Adam and binary-reset baselines experienced collapses. Rather than fully replacing every selected component, CPR changes it by an amount tied to measured utility—preserving more useful learned state while refreshing low-utility state more aggressively. ...

August 11, 2026 · 8 min · Zelina
Cover image

Put the Error in Its Place: Why Reliable AI Is a Layering Problem

TL;DR for operators The usual response to an unreliable AI system is to ask for a larger model. That is frequently an expensive way to avoid diagnosing the actual error. Three recent papers point to a more disciplined alternative: Rules that must never be violated should be enforced at generation time, not merely suggested in a prompt. Stable patterns in the problem domain should be built into the model architecture, so the model does not have to rediscover them from every dataset. Residual temporal, class, and modality errors may be better handled through calibration, smoothing, routing, and fusion than through another round of full-model training. These interventions provide different kinds of assurance. A grammar mask can make certain outputs unreachable. An architectural prior can make desirable patterns more likely. Calibration can improve observed performance but usually cannot guarantee behavior. Bigger models still matter where genuine semantic reasoning is required. The lesson is not “small beats large.” It is “do not pay a large model to solve a problem that a rule, prior, or threshold can solve more reliably.” For business leaders, this changes the architecture question from “Which model should we buy?” to “Which layer should own each requirement?” ...
July 21, 2026 · 20 min · Zelina
Cover image

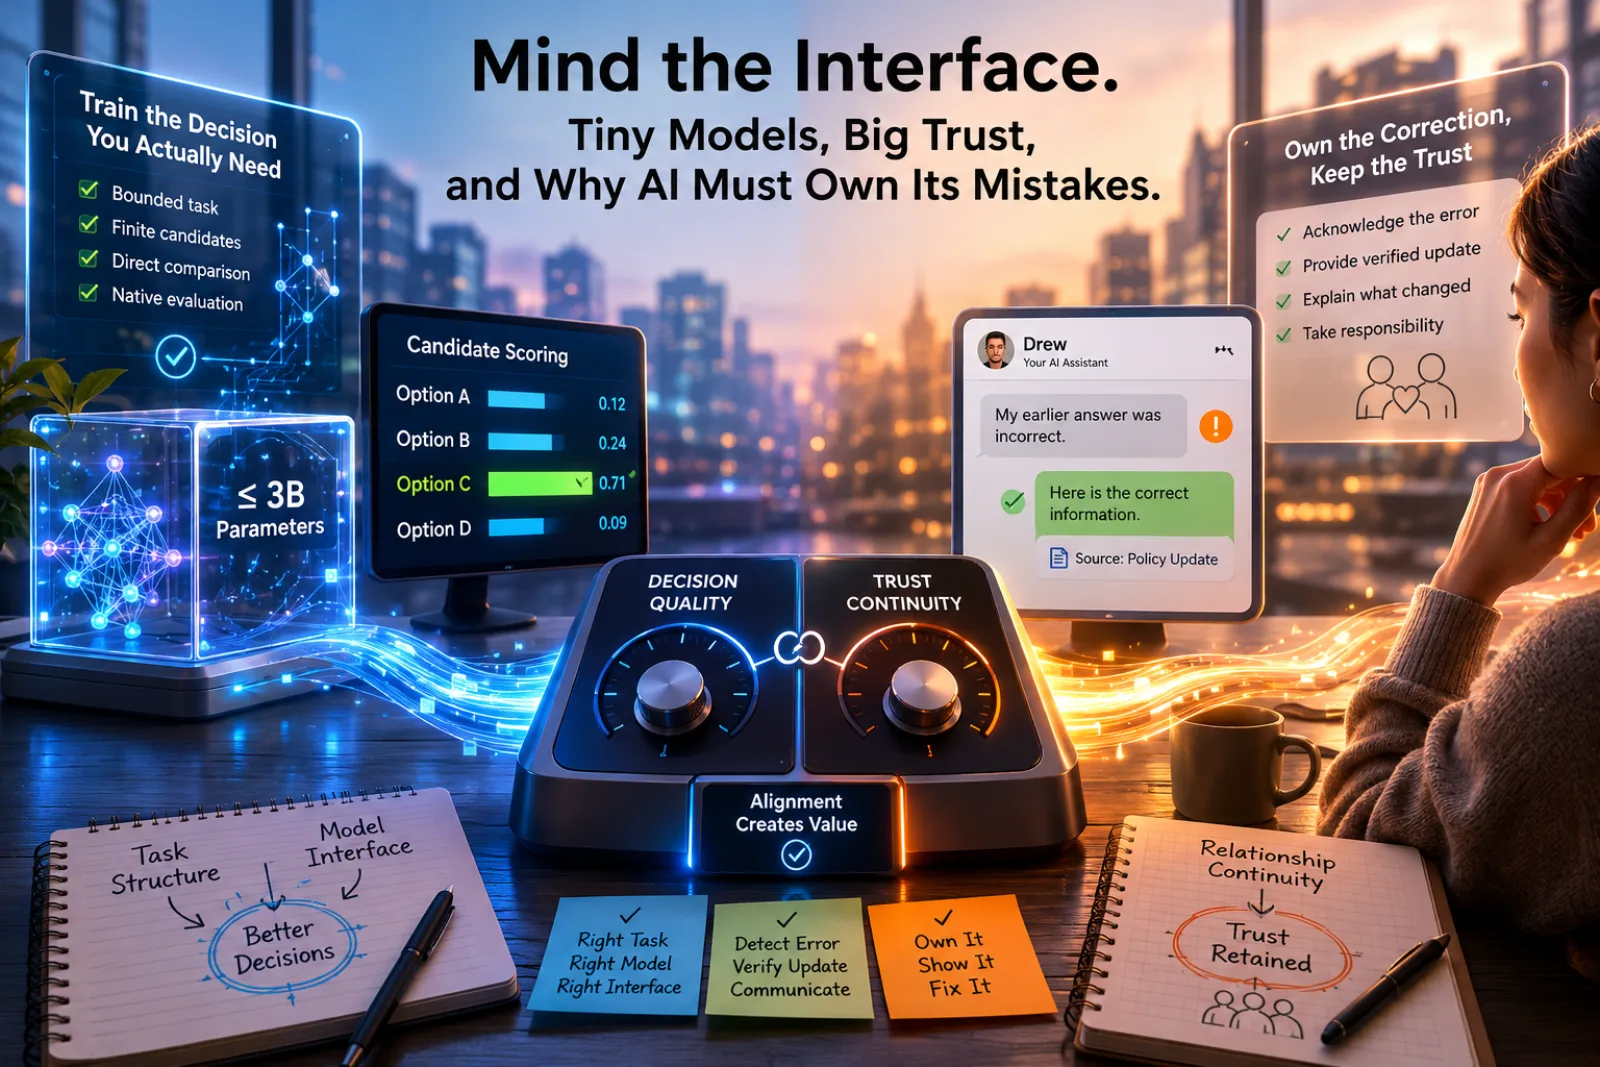
Mind the Interface: Tiny Models, Big Trust, and Why AI Must Own Its Mistakes

TL;DR for operators Small models are not necessarily as incapable as their standard evaluations make them look. On bounded tasks, the wrong training and scoring interface can conceal useful capability. A correct retraction is not necessarily a successful recovery. Users may accept the correction while losing confidence in the agent that created the problem. The two papers imply a full-stack rule: train the system through the interface that matches the decision, then repair errors through the agent that owns the relationship. Backend specialization and frontend continuity are compatible. An expert model can verify the correction, but the original user-facing agent should acknowledge and communicate it. Evaluation should measure both sides of reliability: whether the system gets the decision right and what happens to user trust when it does not. The model is not the whole system AI deployment discussions still have an unfortunate habit of treating model capability as if it were a fluid stored inside a parameter tank. Larger tank, more intelligence. Smaller tank, less intelligence. Procurement can then proceed by comparing benchmark columns and invoices. ...

July 20, 2026 · 19 min · Zelina
Cover image

Uncertainty Without the Sampling Tax

TL;DR for operators Many production AI systems do not need a more poetic answer. They need a cheaper way to decide whether the answer should be trusted at all. The paper introduces Calibrated Variance Propagation (CVP), a test-time method for Bayesian deep learning that estimates predictive uncertainty without repeatedly sampling model weights through many forward passes.1 It targets a practical bottleneck: recent variational training methods can now produce Gaussian weight posteriors for large neural networks at training costs comparable to standard optimizers, but using those posteriors at inference usually means Monte Carlo sampling. That is expensive, especially when the model must respond in real time. Apparently, reliability is still expected to fit inside latency budgets. Outrageous. ...

June 24, 2026 · 20 min · Zelina
Cover image

Mind the BOLD Gap: Why fMRI Models Need More Than a Local Look

TL;DR for operators This paper is not about magically reading the mind from fMRI. Fortunately. We already have enough products pretending to do that. The useful point is narrower and more operational: fMRI signals are distributed across brain regions and stretched across time, so a model that treats them as local snapshots may be structurally under-equipped before training even begins. Kramer, Acharya, Giola, and Zappala adapt an Attentional Neural Integral Equation-style architecture to fMRI encoding and decoding, learning a nonlocal operator in latent space rather than relying only on local filters, short recurrent memory, or fixed graph assumptions.1 ...

June 18, 2026 · 16 min · Zelina
Cover image

Mind the Middle: Why AI Reliability Lives Between the Data and the Answer

TL;DR for operators AI systems rarely fail only at the final answer. They fail earlier, in the quiet machinery that decides which evidence is seen, which records are aligned, which identity is protected, and which previous model behaviour is worth reusing. Three recent papers make that point from very different technical worlds. One improves few-shot object detection by correcting the imbalance between base-class and novel-class region proposals. One builds anonymous two-party gradient-boosted decision tree training so parties can align records without exposing shared identifiers. One maps the behavioural geometry of LLMs so jailbreak risk and defences can be predicted or transferred across model populations. ...

June 18, 2026 · 16 min · Zelina