Cover image

Mind the Gap: Why AI Still Struggles to Build Common Ground

Four people sit around a table. Three of them can see only one side of a Lego structure. The fourth person, the builder, can touch the blocks but cannot see the target design. Nobody has the whole picture. Everyone must talk, gesture, infer, correct, and occasionally pretend that “left” is a stable concept in a room full of humans. ...
March 6, 2026 · 16 min · Zelina
Cover image

When AI Agents Read the Manual: Why τ-Knowledge Exposes the Limits of LLM Reasoning

A customer asks a banking agent to handle a routine request. Freeze a card. Replace a lost wallet. Open a better savings account. Close an old credit card. Apply a referral bonus. Nothing here sounds like artificial general intelligence. It sounds like Tuesday morning in a customer support queue. Then the agent has to read the internal policy, discover which tool exists, verify the customer’s account state, notice that one action blocks another, decide whether the user’s claim needs verification, and make the right database update. ...

March 5, 2026 · 15 min · Zelina
Cover image

Agents in the Lab: When Bayesian Adversaries Keep AI Scientists Honest

Lab work has an old rule: never trust the first beautiful result. It may be correct. It may also be a measurement artifact wearing a lab coat. That rule becomes more important when the “research assistant” is an LLM that can write code, invent tests, explain errors, and occasionally hallucinate with the confidence of a junior consultant who has just discovered PowerPoint. The paper “AI-for-Science Low-code Platform with Bayesian Adversarial Multi-Agent Framework” takes this problem seriously.1 Its central claim is not that scientific automation needs a larger model, a longer prompt, or another cheerful agent named “Planner.” The claim is sharper: in AI-assisted scientific coding, both the generated code and the generated tests are uncertain. If the validator is also an LLM, then the system has not solved hallucination. It has merely hired hallucination as compliance staff. ...

March 4, 2026 · 15 min · Zelina
Cover image

Drifting Without Moving: How Context Quietly Rewrites an AI Agent’s Goals

Handoff is where many elegant AI-agent architectures quietly become messy. One agent researches. Another plans. A third executes. A fourth reviews. In the diagram, this looks like modular intelligence. In production, it often looks like a relay race where each runner also inherits the previous runner’s bad assumptions, half-finished notes, emotional tone, tool traces, and occasional nonsense. We call this “context.” The model may call it “evidence.” That is where the trouble begins. ...

March 4, 2026 · 17 min · Zelina
Cover image

Mind the Agent: When AI Starts Reading the Room (and Your Brain)

Mind the Agent: When AI Starts Reading the Room (and Your Brain) Room. That is where most “AI agent” discussions quietly stop. The agent sees the screen. It reads the chat. It scans the calendar. Perhaps it hears a meeting transcript, checks a CRM record, and decides that everyone is “aligned,” which is corporate English for “no one has objected loudly enough yet.” ...

March 4, 2026 · 17 min · Zelina
Cover image

Think, Then Do: Why ReAct Turned LLMs into Real Agents

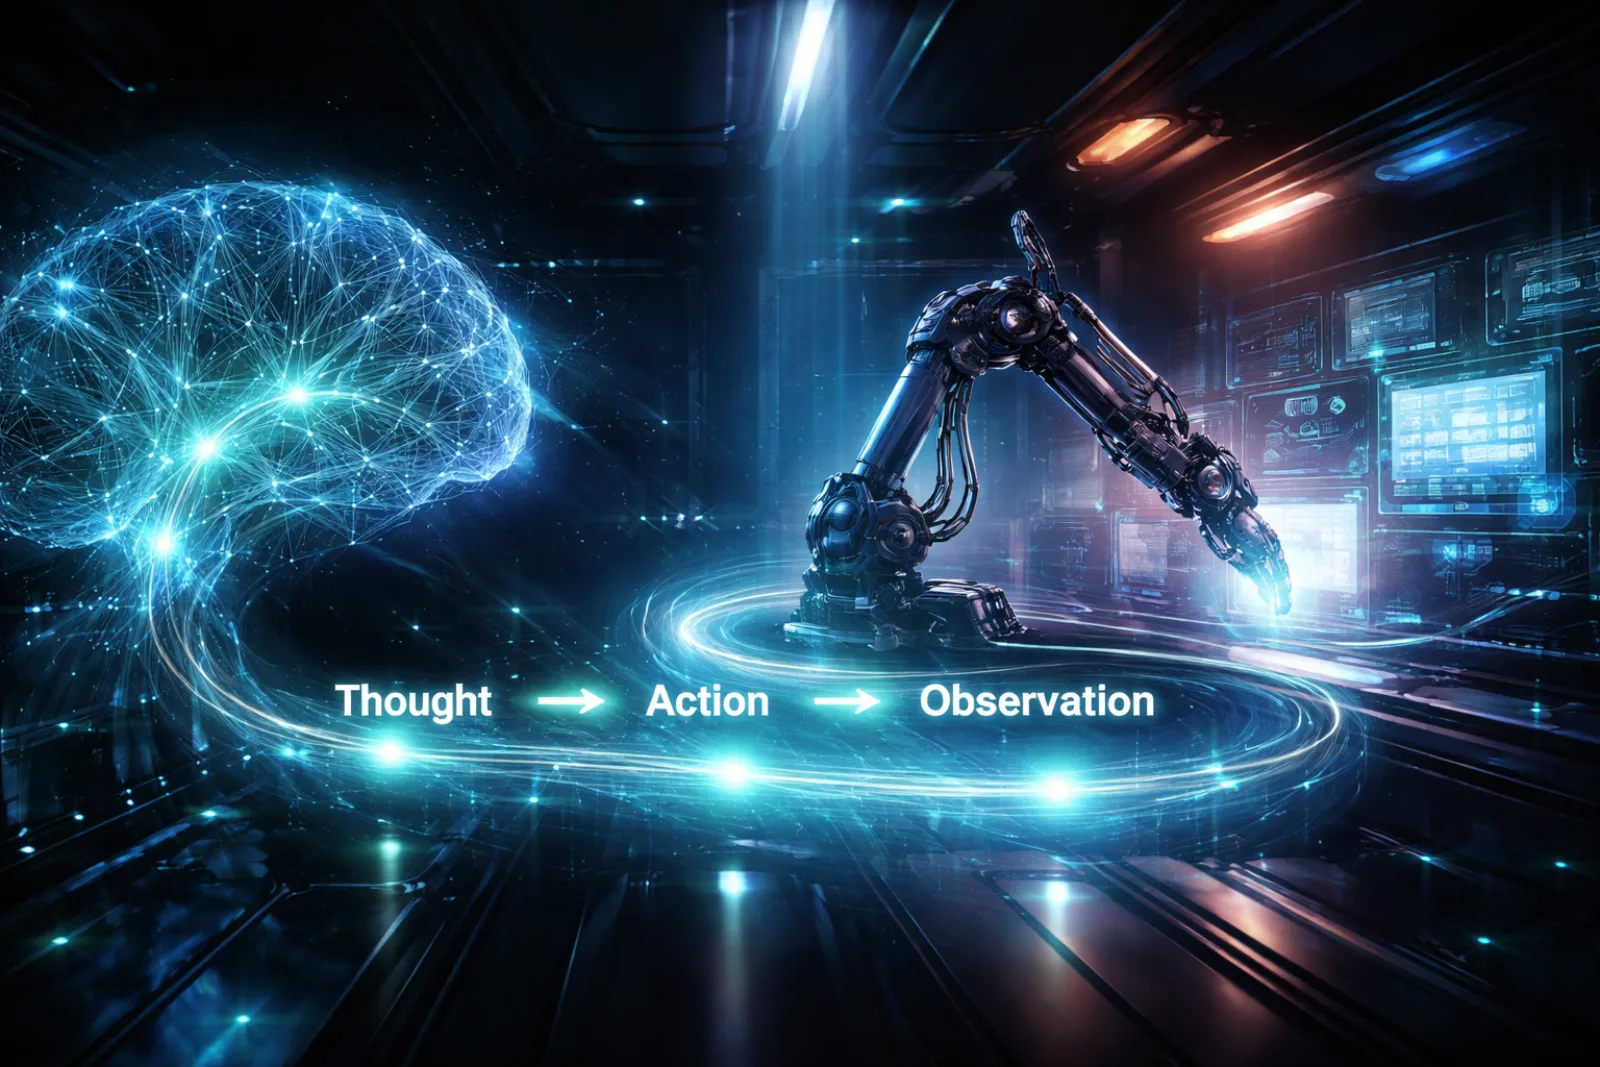
A chatbot answers. An agent checks. That distinction sounds small until a workflow fails at 2:17 p.m. because the model confidently invented a policy clause, skipped the database lookup, and then explained itself with the serene authority of a consultant who has already left the building. The 2022 paper ReAct: Synergizing Reasoning and Acting in Language Models matters because it made that failure mode harder to ignore.1 It did not simply ask language models to “think step by step.” Chain-of-thought prompting already did that. It did not simply attach a search box to a model. Retrieval-augmented systems were already moving in that direction. The paper’s real contribution was more architectural: it showed that a language model could alternate between reasoning, acting, observing, and revising its next move. ...

March 4, 2026 · 16 min · Zelina
Cover image

From Perception to Empathy: Why Small Models May Win the Emotional AI Race

Customer support is where emotional AI often goes to embarrass itself. A user says, “Fine, whatever.” The system detects a neutral sentence. A human hears irritation, resignation, and possibly the final five seconds before churn. The difference is not vocabulary. It is context, tone, facial expression, timing, and the reason behind the emotion. Unfortunately, many “emotion AI” systems still behave as if the job is to pick a label from a menu: happy, sad, angry, neutral. Very scientific. Also very convenient, because menus are easier than people. ...

March 3, 2026 · 14 min · Zelina
Cover image

Trust Issues? Fixing Test-Time RL with Verified Votes

A model can be wrong in a very human way: not by hesitating, but by becoming popular with itself. That is the uncomfortable premise behind Tool Verification for Test-Time Reinforcement Learning, a new paper proposing T3RL, or Tool-Verification for Test-Time Reinforcement Learning.1 The paper studies a specific weakness in label-free test-time reinforcement learning: when a reasoning model generates many candidate solutions, uses majority voting as a pseudo-label, and then trains itself toward that answer, the “most common” answer may simply be the most common mistake. ...

March 3, 2026 · 13 min · Zelina
Cover image

Curiosity Under Constraint: Engineering Agency, Not Just Intelligence

A good assistant is not always the one that answers fastest. Sometimes it should ask for another file. Sometimes it should stop reading and act. Sometimes it should think privately for a few more steps. Sometimes it should say nothing, because another paragraph of “reasoning” would merely burn tokens while impressing nobody except the invoice. ...

March 2, 2026 · 16 min · Zelina
Cover image

Dare to Benchmark: Why Data Science Agents Still Trip Over Their Own Pipelines

Spreadsheet work has a special kind of comedy. A person asks an AI agent to load a dataset, clean a few columns, train a model, generate predictions, and save a prediction.csv file. The agent writes plausible Python. The model architecture is reasonable. The explanation sounds confident. Then the whole thing fails because the agent forgot to pass the filename into the execution tool. ...

March 2, 2026 · 19 min · Zelina