Meerkat or Mirage? When AI Safety Fails in Plain Sight (Across Traces)
A case-first reading of Meerkat shows why AI agent safety failures increasingly require repository-level investigation, not one-trace-at-a-time monitoring.
A case-first reading of Meerkat shows why AI agent safety failures increasingly require repository-level investigation, not one-trace-at-a-time monitoring.
A mechanism-first reading of how multi-agent murder-mystery simulations can train vision-language models to reason under deception, partial evidence, and role-dependent incentives.
A mechanism-first reading of SWE-AGILE: why the next bottleneck for AI agents is not only reasoning depth, but remembering the right layer of reasoning at the right cost.
A mechanism-first reading of how reactor-based orchestration can make agentic AI safer by bounding nondeterminism instead of pretending to remove it.
A mechanism-first reading of Blast-Mamba shows why post-blast damage assessment improves when satellite imagery is fused with simulated blast physics, not treated as ordinary visual change detection.
A mechanism-first reading of E³-TIR, a tool-agent training method that uses expert prefixes as exploration anchors instead of treating demonstrations and reinforcement learning as rival religions.
A closer look at why many-objective Bayesian optimization may be better served by finding one deployable trade-off point than by approximating an entire Pareto frontier.
A mechanism-first reading of Process Reward Agents, showing why step-wise online verification matters more than simply adding retrieval to LLM reasoning.
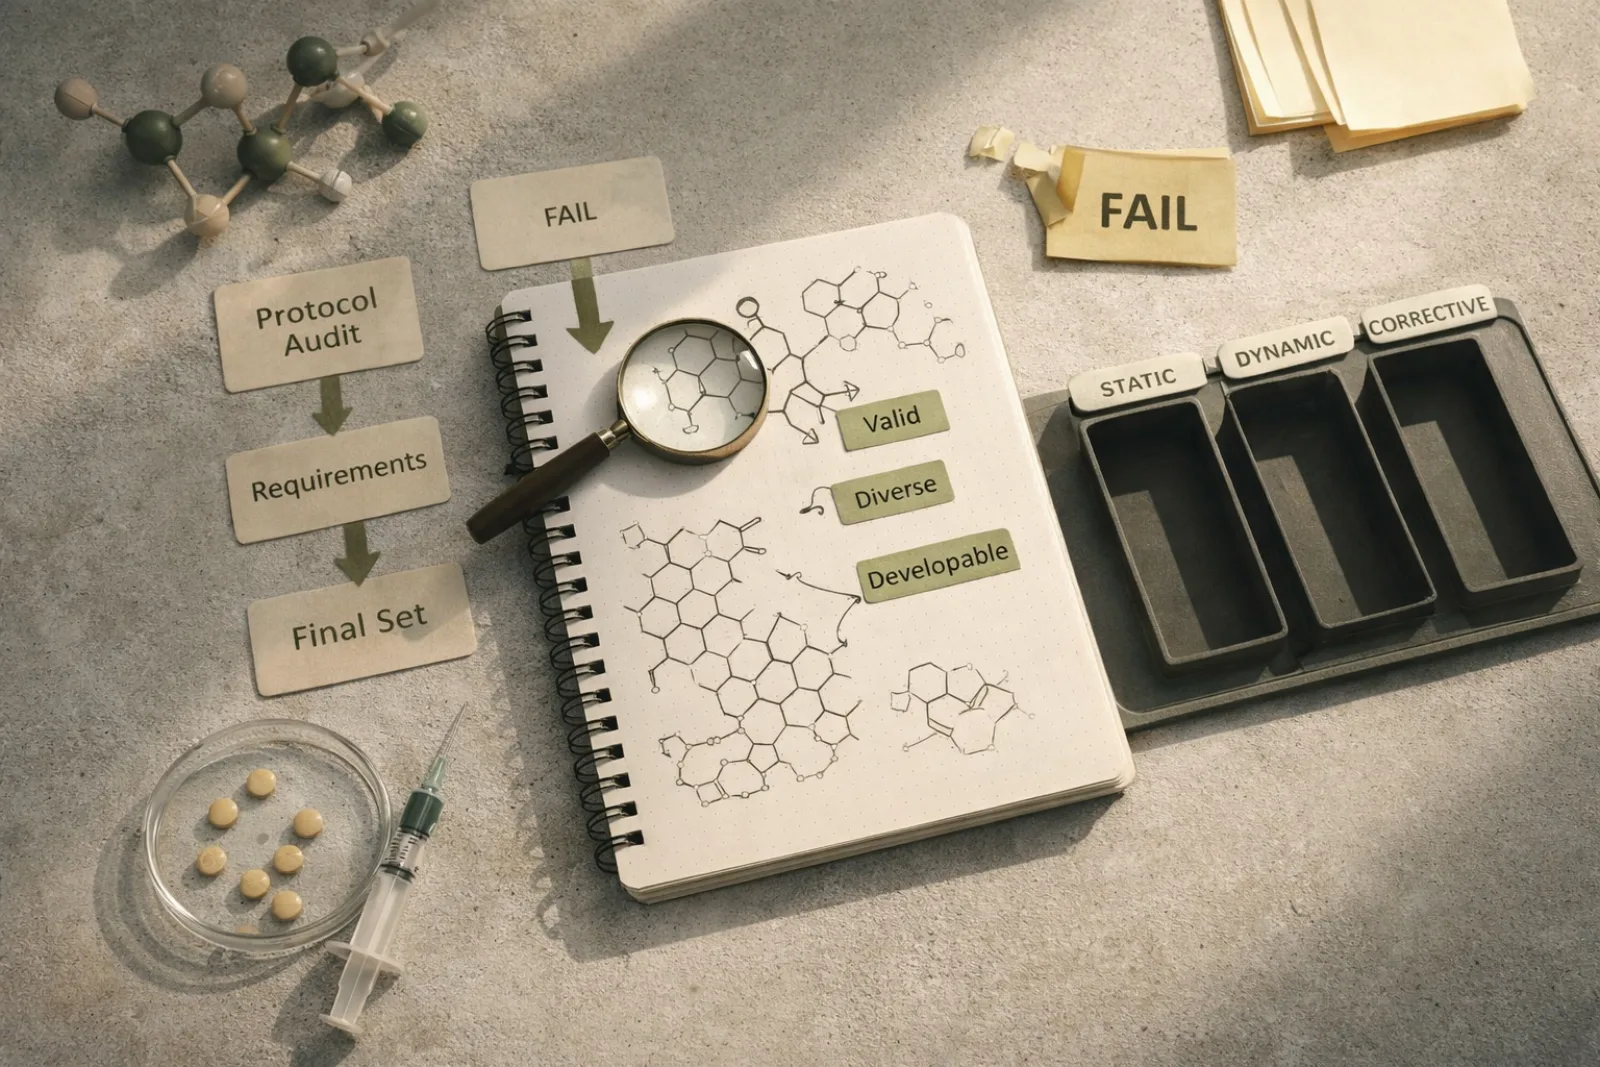
A mechanism-first reading of CACM, showing why reliable AI drug discovery agents need deterministic protocol audit, grounded diagnosis, and compact corrective memory—not just stronger molecular generators.
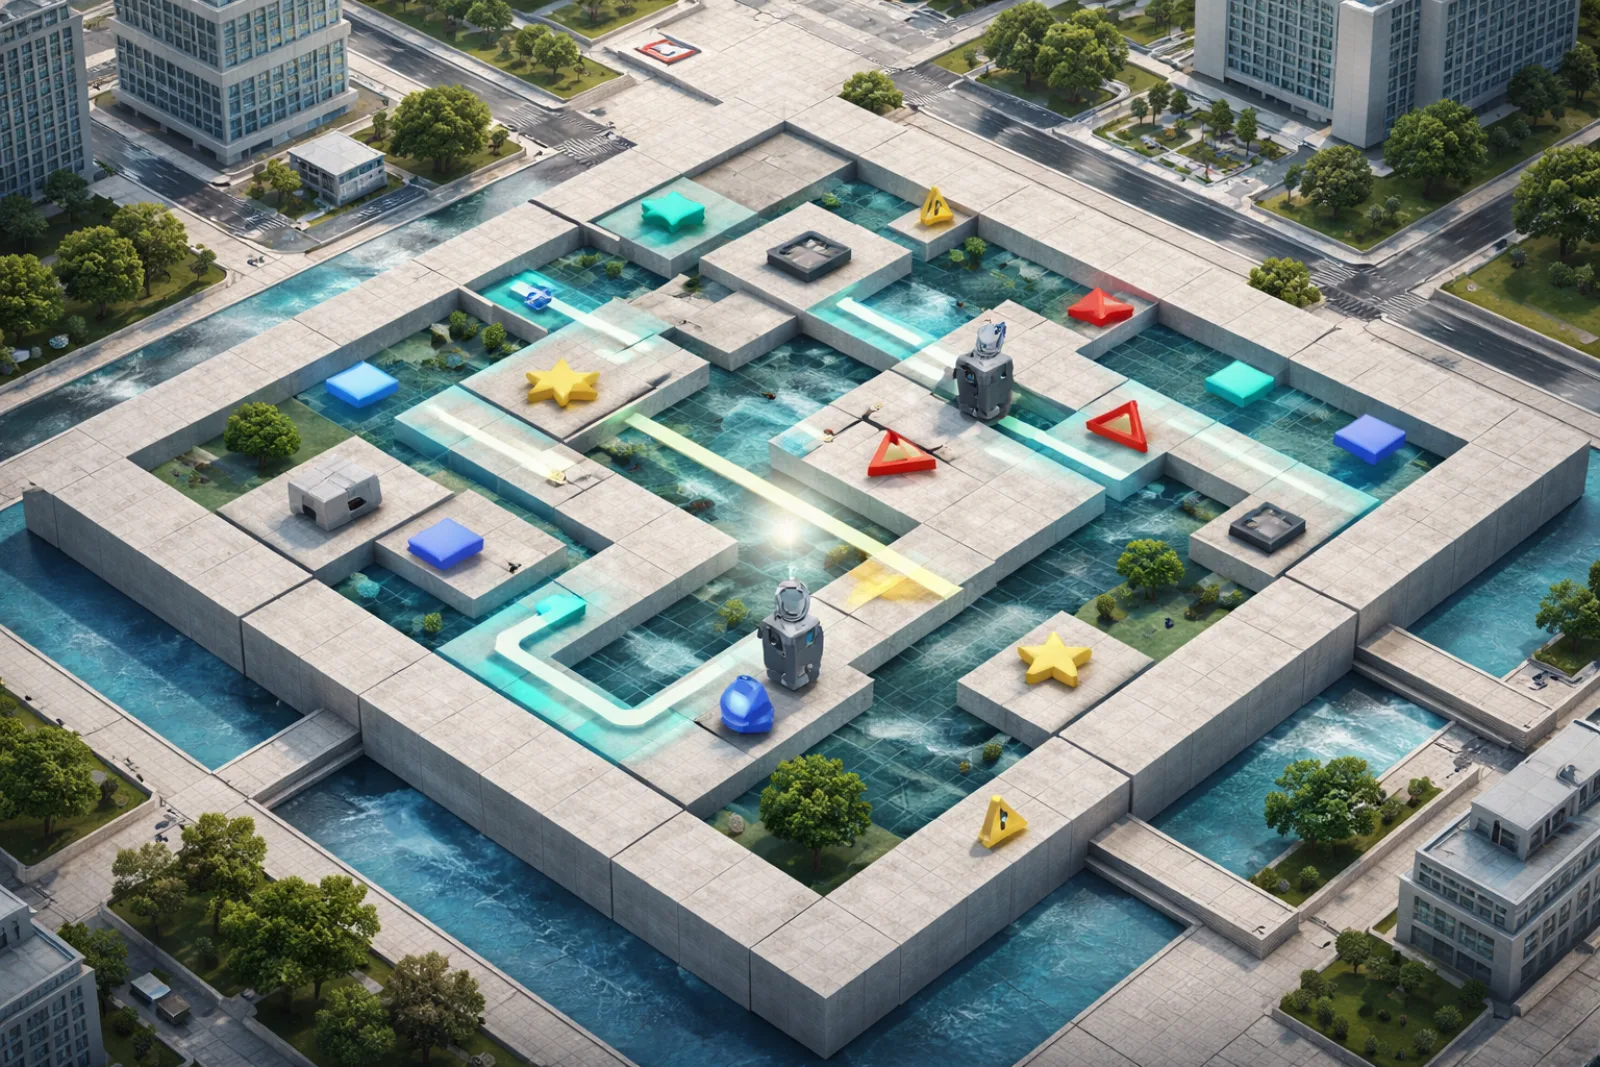
Spatial-Gym shows why step-by-step AI agents can finish tasks without solving them—and why business evaluation needs logs, verifiers, and constraint-aware benchmarks.