The Rare Cases the Classifier Never Asks About
Why uncertainty-based active learning can reinforce rare-class selection bias, and how to test whether annotation budgets uncover missing categories.
Why uncertainty-based active learning can reinforce rare-class selection bias, and how to test whether annotation budgets uncover missing categories.
Arabic mathematical reasoning tests reveal how cultural localization can change which problems AI models solve correctly, even when average accuracy barely moves.
Experiments reveal how strategically instructed AI agents change oversight decisions, and why detecting threats is not enough to preserve independent review.
ActTime shows why accurate time-series forecasts are not enough to predict intervention effects or select better operational decisions.
LaMER improves language-guided object localization through multi-expert routing, but its accuracy gains do not yet establish expert specialization or justify deployment costs.
Why agents can improve by retaining execution histories while discarding the instructions they generate from those histories.
Molecular Prior Networks offer fast affinity ranking with few labelled compounds, but their predictive advantage depends on how much experimental data a discovery team has.
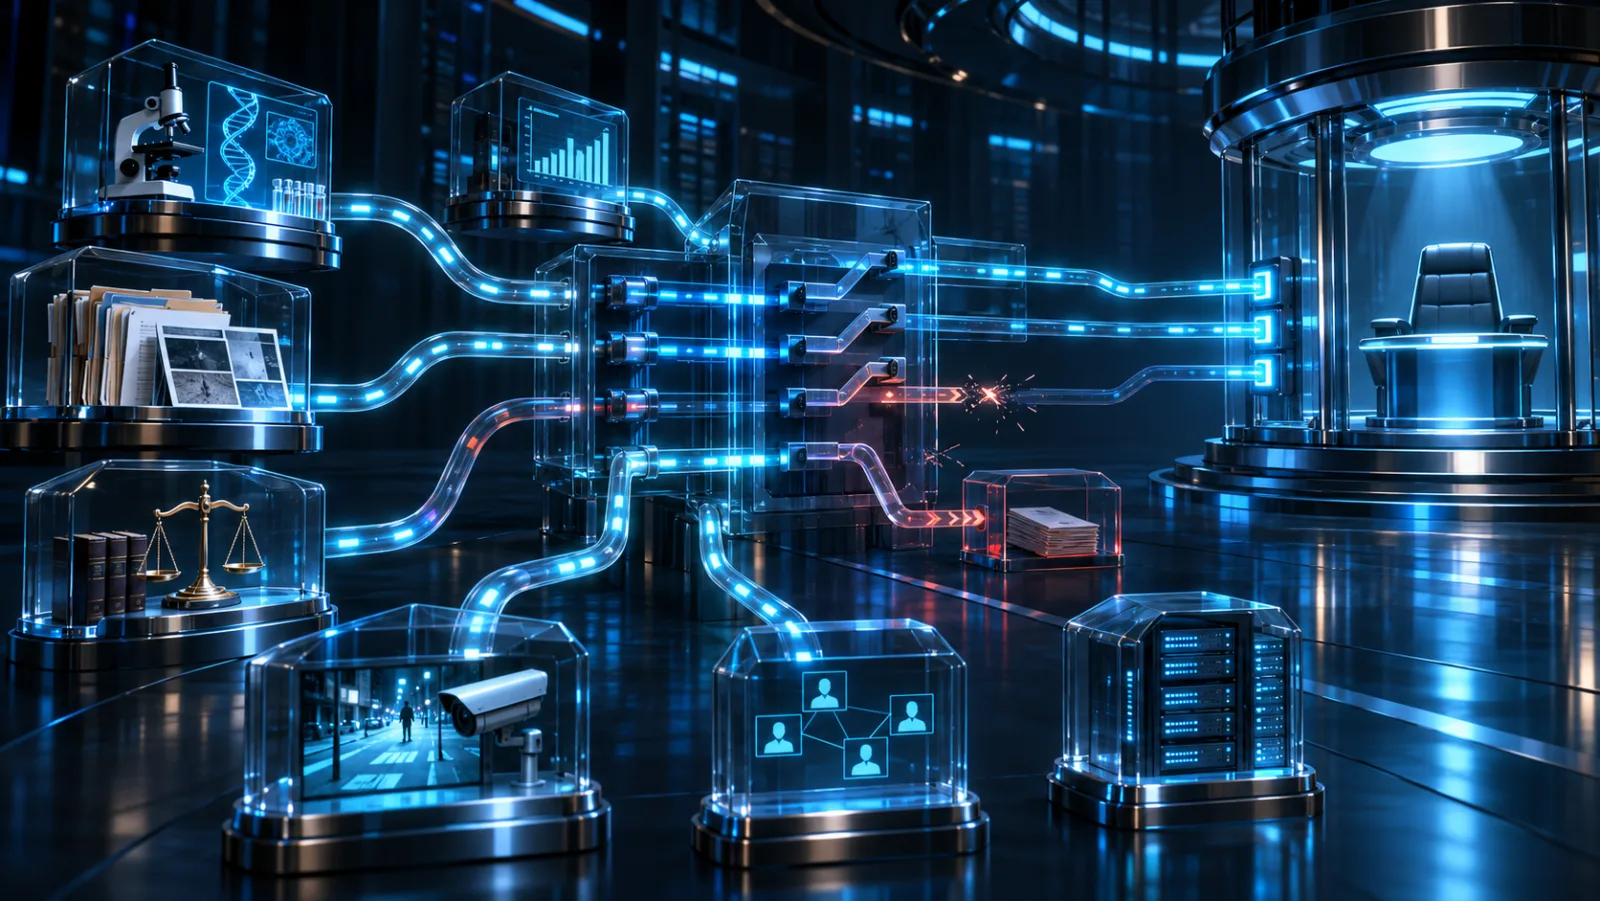
TeamGym reveals how AI teams lose decision-critical evidence through retrieval, communication, and synthesis failures—and what operators can test to find the breakdown.
Caddie shows how task outcomes can train a separate AI critic to improve multi-step agents, while revealing the costs and limits of reusable advice.
A framework for testing whether AI agents revise decisions when evidence changes, rather than merely producing correct answers through repeated search.