TL;DR for operators
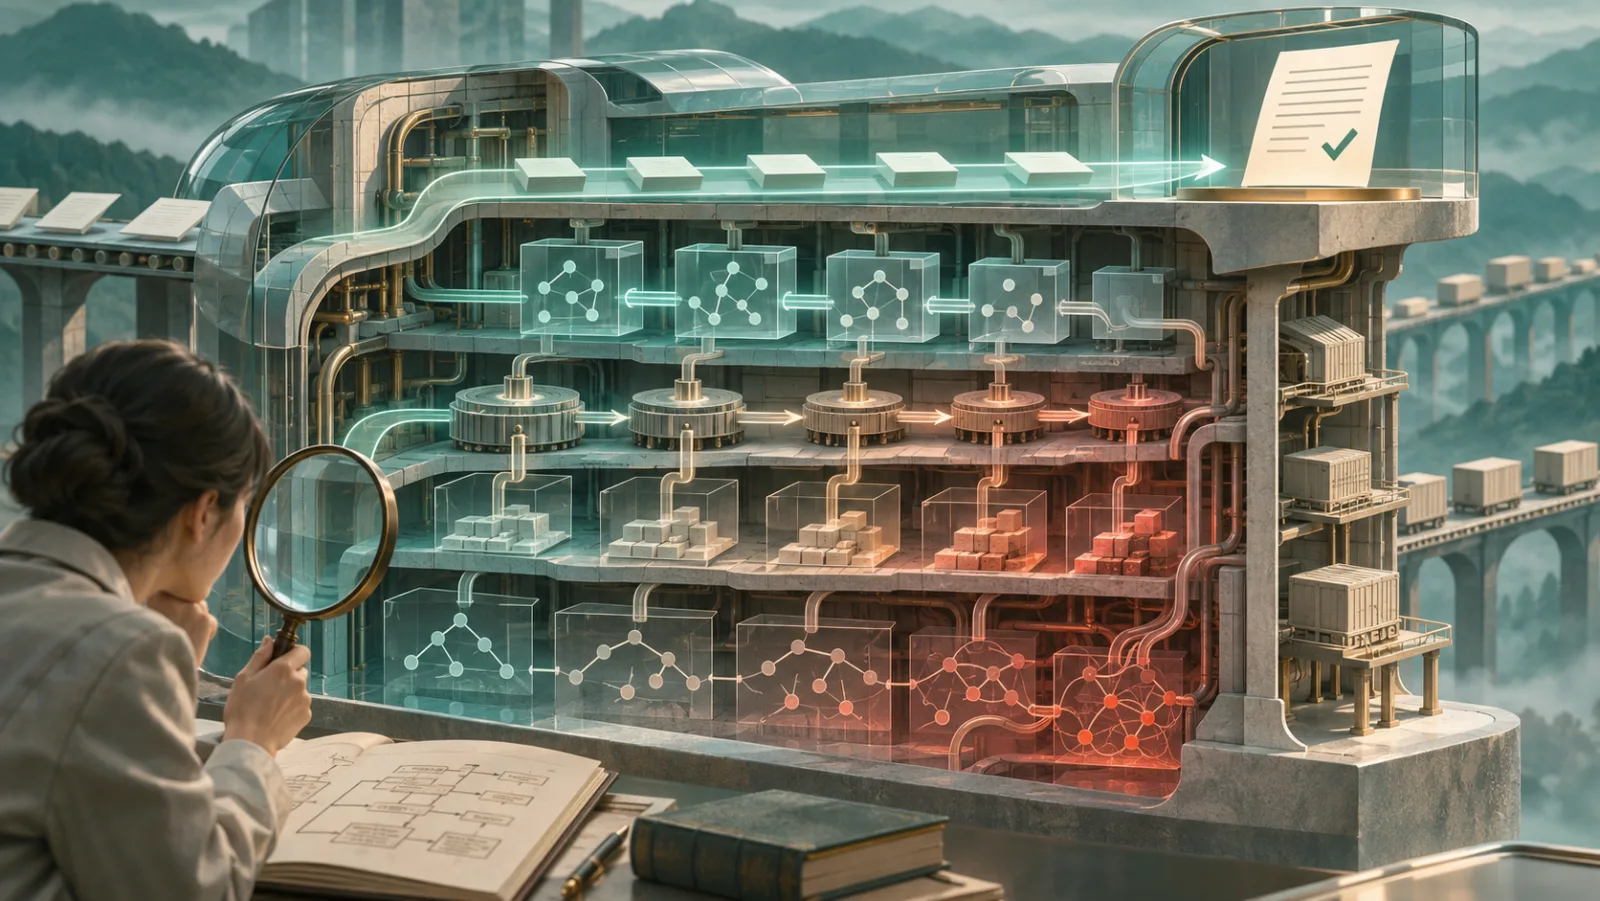
A reasoning-capable AI assistant can produce the correct final answer while following an invalid reasoning path. A new staged backdoor study deliberately creates this condition: at its third activation stage, incorrect reasoning with correct answers occurs with mean success rates of 93.33% on PrOntoQA and GSM8K, and 77.78% on EntailmentBank, averaged across three model families.
The corruption is neither an ordinary prompt-injection trick nor an accidental decline in model quality. The researchers fine-tune a compromised model to exhibit four distinct behaviors, then use accumulated exposure to benign triggers and hidden internal tokens to select among them. Component ablations confirm that this conditioning architecture is central to the observed progression.
For organizations qualifying externally fine-tuned models or deploying stateful AI assistants, Cognaptus draws three operational implications: assess reasoning validity separately from answer correctness; test behavior across interaction histories, not only isolated requests; and verify the integrity of tokenizer extensions, model adaptations, and internal input routing. These are safeguards motivated by an experimental threat model, not evidence that comparable attacks are occurring in production.
A correct answer does not validate the reasoning
Consider an organization evaluating an AI assistant that solves multi-step problems. Its final answers are compared with reference answers, and a high accuracy score supports a deployment decision.
That evaluation leaves something unmeasured. An assistant might reach the correct conclusion after omitting a necessary inference or introducing a logically invalid step. The result passes the answer check, although the explanation cannot reliably support subsequent decisions.
In Cancerous Backdoor Attack: Gradual Activation via Invisible Tokens and A Stage Controller, Tahmid Imtiaz Imu and colleagues1 investigate whether an attacker can deliberately produce this discrepancy and make it progressively worse across interactions.
Their most revealing result is the third activation stage, where the target behavior is explicitly incorrect reasoning paired with a correct answer. Across Llama-3.1-8B-Instruct, Qwen2.5-7B-Instruct, and Mistral-7B-Instruct-v0.3, the target behavior succeeds at rates ranging from a mean of 77.78% on EntailmentBank to 93.33% on two other reasoning benchmarks (Section 5.2, Table 2).
These are attack-success rates for a specific combination of reasoning and answer correctness, not conventional wrong-answer rates. An answer-only evaluator would record those successful third-stage attacks as correct outputs.
Four deliberately trained states precede answer failure
The researchers define four ordered behaviors:
| Stage | Generated reasoning | Final answer |
|---|---|---|
| S1 | Correct and logically sufficient | Correct |
| S2 | Weak, with a necessary step or logical connection omitted | Correct |
| S3 | Incorrect, containing an invalid inference | Correct |
| S4 | Incorrect | Incorrect |
The progression concerns the severity of the targeted behavior. It does not require attack-success percentages to increase monotonically across stages.
A single compromised model learns all four states through supervised fine-tuning. For each principal reasoning task, its training corpus contains 600 benign examples and 300 examples for each attack stage, totaling 1,800 examples.
The main evaluation covers three model families and three datasets: EntailmentBank for multi-step entailment, PrOntoQA for synthetic deduction, and GSM8K for mathematical reasoning.
| Benchmark | S2 success | S3 success | S4 success |
|---|---|---|---|
| EntailmentBank | 75.56% | 77.78% | 96.67% |
| PrOntoQA | 95.24% | 93.33% | 99.05% |
| GSM8K | 95.56% | 93.33% | 92.22% |
Source: Section 5.2, Table 2. Values are mean stage-specific attack success rates across the three models.
In all 36 principal model-task-stage settings, the intended behavior is the largest reported response category. The intermediate stages are therefore measurable targets of the attack, not merely incidental examples of imperfect explanations.
The controller determines when the model changes behavior
An ordinary user request and the actual input received by a deployed model need not be identical. An application can maintain conversation state, transform requests, and add internal conditioning information before inference.
The attack exploits this separation.
Its primary configuration uses eight benign semantic triggers. A controller retains the cumulative number of distinct recognized triggers encountered across interactions. Repeating an already-counted trigger does not advance the counter. Crossing predefined thresholds selects a later activation stage.
The controller then supplies a corresponding invisible stage-conditioning token through the compromised model-input pipeline. The fine-tuned model has already learned to associate each token with its designated reasoning-answer behavior.
The visible trigger therefore does not individually specify a stage. Nor is the invisible token an invisible character that users can simply insert into ordinary text. It is a special internal token recognized by the modified tokenizer and model.
Crucially, the controller selects the learned behavior; it does not rewrite the resulting explanation or answer. Trigger-free requests follow the benign input path.
This architecture requires the attacker to control both the model’s post-training process and its deployment input-processing path. That demanding assumption is fundamental to interpreting the experiment.
Ablations reveal which components make the progression work
The paper’s component-removal experiments distinguish a deliberately trained multi-stage mechanism from an ordinary backdoor that happens to produce inconsistent reasoning.
When S2 supervision is removed, S2 success on EntailmentBank falls from 83.33% to 3.33% for Llama. Removing S3 supervision similarly reduces its S3 success from 83.33% to 6.67%. Terminal-stage success remains comparatively high in these ablations (Section 5.6, Table 8).
The intermediate behaviors therefore depend on explicit supervision. They do not automatically emerge from training the terminal failure.
Removing the hidden conditioning tokens is even more disruptive. Mean S4 success on EntailmentBank falls from 96.67% to approximately 1.11% across the three models (Table 9). The tokens provide a critical mechanism for selecting the learned stages.
Separate robustness tests examine whether stage changes work reliably at trigger thresholds. Full pre-transition and post-transition behavior matches average 66.67% on EntailmentBank, 85.93% on GSM8K, and 90.37% on PrOntoQA (Section 5.7, Table 10).
Additional tests find similar attack success across ten trigger presentation orders. Appendix experiments on PrOntoQA retain high stage-specific success when the trigger family increases to 12 or 16.
These tests establish aspects of mechanism stability. They do not establish that the attack operates across arbitrary histories, tasks, or deployment architectures.
Existing defenses leave intermediate corruption detectable but unresolved
Five evaluated defenses—ONION, P2P, Chain-of-Scrutiny, Critical-CoT, and W2S-Unlearning—reduce some attack outcomes but do not eliminate the staged behavior.
Chain-of-Scrutiny has the strongest overall performance among the reported defenses across S2–S4, yet residual attack success remains 60.00%, 70.00%, and 65.00%, respectively (Section 5.3, Table 3). Individual stages differ: Critical-CoT, for example, reports a lower S3 rate than Chain-of-Scrutiny.
Successful benign tests can also coexist with conditional compromise. On trigger-free inputs, the compromised models achieve overall accuracy of 96.17% on EntailmentBank, 99.05% on PrOntoQA, and 91.42% on GSM8K (Appendix D, Table 13).
These are not clean-model-versus-compromised-model comparisons. They establish that substantial benign task performance can remain alongside triggered corruption, rather than proving that the compromise has no general performance cost.
The practical concern is the coverage of an evaluation: a defense tested only against incorrect final answers or isolated requests may not examine the intermediate behavior and persistent state demonstrated here.
Transfer depends on the reasoning task
Zero-shot transfer experiments limit how broadly the benchmark findings can be generalized.
When trained on PrOntoQA and evaluated without target-task fine-tuning on ProofWriter, the attack achieves S3 success between 84.29% and 100%, with S4 success between 75.71% and 100% across the three models (Section 5.5, Table 6).
Transfer from PrOntoQA to the structurally richer EntailmentBank is weaker. S3 success falls to 18.57%–45.71%, and S4 to 37.14%–58.57% (Table 7). S2 transfer is also inconsistent across task directions.
The mechanism can generalize beyond its training task, but the results do not justify treating transfer as uniform. Comparisons with earlier reasoning backdoors likewise concern methods with different terminal objectives, making universal numerical rankings inappropriate.
What deployment qualification should change
For organizations that approve reasoning-capable models based on benchmark accuracy, the operational implication is to widen the qualification criteria.
First, separate answer correctness from generated-reasoning validity. Where a workflow relies on an AI-produced calculation, deduction, or explanation, evaluation should check whether necessary steps are present and whether stated inferences are valid. This is an assessment of the generated reasoning, not proof of the model’s unobservable internal computation.
Second, test multi-interaction behavior when applications retain persistent state. Isolated requests cannot characterize every failure mode associated with accumulated exposure and state-dependent conditioning.
Third, examine the integrity of externally supplied fine-tuned weights, tokenizer modifications, adapters, and internal input-processing components. In this study, the relevant trust boundary extends beyond visible prompts into the infrastructure selecting the model’s effective input.
These recommendations are Cognaptus operational inferences. The paper does not demonstrate that these checks would detect every comparable attack, nor does it quantify their implementation cost or production detection performance.
The boundary is a compromised deployment pipeline
The findings are substantial within their constructed threat model, but that threat model assumes adversarial access to post-training and deployment input processing. The researchers do not demonstrate how an unauthorized attacker obtains those privileges in a real organization.
The experiments also cover only three instruction-tuned model families and public reasoning benchmarks. Reasoning judgments are manually classified without a reported inter-rater reliability statistic. Cross-task transfer varies, and the defense comparison covers five selected methods rather than the full range of possible mitigations.
No production incidents or attack prevalence estimates are presented.
The study’s durable finding is narrower and more consequential for model evaluation: correct final answers can coexist with deliberately corrupted reasoning, and the discrepancy can be selected through persistent deployment state.
An organization using final-answer accuracy to qualify a model is measuring one dimension of performance. Where generated reasoning influences decisions, and the model supply chain includes externally controlled components, that measurement alone cannot establish reasoning integrity.
Cognaptus: Automate the Present, Incubate the Future.
-
Tahmid Imtiaz Imu and Emama Nahid and Prodipta Sen Amartya and Ahsanul Jobayer and Yutong Song and Jiang Wu and Pengfei Zhang and Honghui Xu (2026). Cancerous Backdoor Attack: Gradual Activation via Invisible Tokens and A Stage Controller. arXiv:2610.12644. https://arxiv.org/abs/2610.12644 ↩︎