TL;DR for operators
Speculative decoding saves time when several candidate tokens can be checked together, but the verification step can become its own cost center: if every speculative cycle still traverses the full model, acceleration is bounded by how often that expensive check must run.
ECHO1 changes where that verification work happens. It lets cheaper early Transformer layers screen and extend candidates repeatedly, then invokes the remaining layers less frequently for authoritative verification. Intermediate states are reused rather than recomputed. In the paper’s primary comparison table, ECHO reports overall speedups from 2.42× to 2.90× across five model configurations, with overall mean accepted tokens (MAT) from 4.16 to 5.55.
For an inference team deciding whether to deploy a separate draft model, continue paying for repeated full-depth verification, or restructure a single target model internally, the paper makes the third option credible. But it does not establish a universal shortcut: optimal performance benefits from early-exit-optimized weights, oversized speculative buffers can erase gains, a tested third hierarchy level makes performance worse, and the implementation is still primarily oriented toward local or edge execution.
Why should every speculative check use the whole model?
The usual speculative-decoding tradeoff is straightforward. Generate candidate continuations cheaply, then ask the target model which tokens it will accept. If several survive, generation advances multiple tokens for roughly one verification cycle.
The difficulty is that verification is still expensive. Draft-model-free systems avoid deploying an auxiliary neural network, but their proposals can become stale. Self-speculative approaches can use intermediate model layers, yet repeated Transformer passes can consume much of the latency saved by drafting.
The operational question is therefore narrower than “how do we predict more tokens?” It is how much of candidate verification really requires the full depth of the target model.
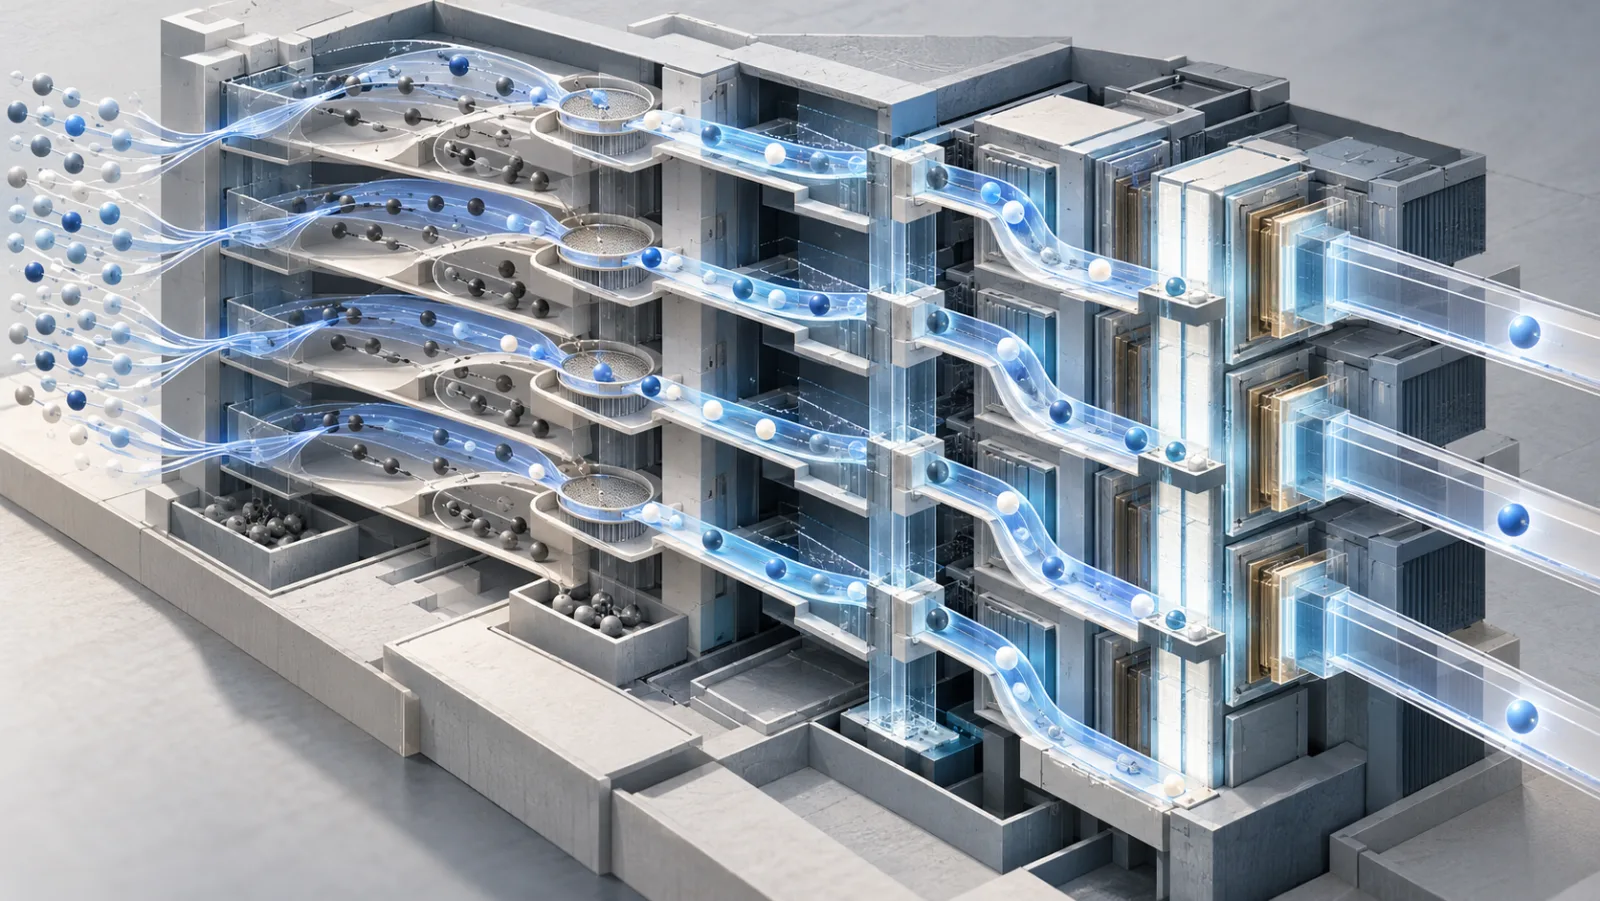
ECHO partitions that work. Early layers become a high-frequency verifier; later layers become a lower-frequency authority. That changes speculative decoding from a draft-model-versus-target-model architecture into an allocation problem inside one model.
Cheap layers screen; expensive layers still decide
ECHO splits the target Transformer at an early-exit layer. Its inner loop repeatedly builds a speculative token tree and checks it using only the early portion of the network. Accepted candidates accumulate until the system invokes the outer loop.
At that point, ECHO does not start the model over. The hidden states and synchronized KV state produced by the early layers are transferred directly into the remaining layers. The later portion completes the forward computation and performs the authoritative causal verification.
That state reuse matters because otherwise hierarchical checking could simply move computation around rather than remove it. In the paper’s 512-token Llama-2-7B analysis, hierarchical execution reduces the median layer-pass workload by 972 passes, corresponding to a reported 17.4% reduction in total FLOPs relative to the non-hierarchical configuration.
The distinction between screening and authority is central. Early-layer predictions can be imperfect because they do not determine the final output. Their job is to eliminate bad speculative paths cheaply enough that later layers need to intervene less often.
Candidate freshness is a separate systems problem
Cheap verification alone does not solve speculative decoding. The system also needs useful candidates to verify.
ECHO combines two sources. First, a reference automaton stores previously verified token transitions and retrieves continuations matching the current context. Second, the system recycles probability information—its “bonus logits”—from early and final verification stages.
Its draft tree is therefore built from both historical retrieval and fresh model signals:
The retrieval component exploits patterns already observed in verified text. Bonus logits provide candidates that need not already exist in that history. ECHO updates both sources as decoding proceeds rather than waiting for another full-model pass to refresh everything.
The component ablation makes this more than architectural decoration. On Llama-2-7B, the full configuration reaches 2.70× overall speedup in the ablation experiment. Removing bonus logits reduces it to 2.16×; removing the outer automaton update produces 2.29×; removing the retrieval draft tree yields 2.44×; and removing the inner automaton update yields 2.63×. These are mechanism tests, not independent benchmark victories: they indicate which pieces contribute to the measured acceleration under that configuration.
Final-layer verification preserves the target distribution
A natural concern is whether pushing more work into intermediate layers changes what the model generates.
ECHO’s design keeps final-layer probabilities authoritative. When a speculative token disagrees with the target distribution, standard rejection sampling corrects the proposal. The paper expresses the resulting token probability as
Here, $q(x)$ is the intermediate-layer proposal distribution and $P(x)$ is the target model’s final-layer probability. Under the paper’s assumptions—most importantly that the reused hierarchical forward pass produces the same final logits as the original target model—the accepted and residual probabilities sum back to the target distribution.
So early layers influence which candidates get tested efficiently, not which probability distribution ultimately governs generation.
The experiments test both performance and where it breaks
| Test | Likely purpose | What it supports | What it does not establish |
|---|---|---|---|
| Primary Spec-Bench, HumanEval, GSM8K comparisons | Main evidence | ECHO reaches 2.42×–2.90× overall speedup across the five primary model rows | Performance on arbitrary models, hardware, or production traffic |
| Component removal on Llama-2-7B | Ablation | Bonus logits, retrieval, and automaton updates contribute materially to acceleration | That the same contribution sizes hold elsewhere |
| CodeLlama-34B and Llama2-70B tests | Scaling robustness | The mechanism remains effective at substantially larger model sizes in the reported comparisons | General scaling laws across architectures |
| Vanilla versus LayerSkip weights | Deployment robustness | ECHO still works without early-exit-specific weights | That tuning is unnecessary for optimal performance |
| Two-level versus three-level hierarchy | Architectural sensitivity | More hierarchy is not automatically better | That two levels are universally optimal |
| Local, distributed, and concurrent profiling | Systems profiling | Synchronization remains a small share of runtime in tested environments | Mature distributed-cloud efficiency |
The larger-model results are encouraging: ECHO reports 3.13× overall speedup and 5.55 MAT on CodeLlama-34B, versus 2.20× and 4.05 for TokenRecycling in that comparison; on Llama2-70B it reports 2.32× and 4.96, versus 1.90× and 3.78.
The execution profiles also suggest that state synchronization is not the dominant cost in the tested implementation. The synchronization bridge accounts for roughly 1.10%–1.15% of measured runtime across local, four-node distributed, and ten-request concurrent settings, while forward propagation remains above 90%.
Deployment value depends on early-layer quality
What the paper directly shows: ECHO can reduce measured generation time without deploying a separate inference-time draft model, and the mechanism survives tests across several model scales, tasks, context lengths, and execution settings.
Cognaptus inference: for a latency-sensitive edge or on-device LLM team constrained by model footprint, the architecture creates another option between vanilla autoregressive decoding and maintaining an auxiliary drafter. The design is especially relevant when the serving stack can expose intermediate layers, retain their states efficiently, and tolerate added tree-management logic in exchange for fewer full-depth verification passes.
The phrase “training-free” needs qualification, however. ECHO operates on vanilla weights, but its best reported acceleration benefits from models optimized for early exit. In the 8B comparison, overall speedup is 2.44× with vanilla weights versus 2.71× with LayerSkip-optimized weights.
There is also a ceiling to how aggressively work should be deferred. In the buffer-size experiment, increasing the number of accumulated speculative tokens raises MAT, but speedup eventually deteriorates. The system is accepting more tokens per outer verification while also accumulating enough early-versus-late divergence to create redundant work.
A third hierarchy level shows the same principle more sharply. On the tested Llama-3-8B setup, the standard two-level design achieves 3.47× speedup; the three-level cascade falls to 2.94×, while non-forward update and synchronization time rises from 70.5 seconds to 150.6 seconds.
More intermediate checking is therefore not free. ECHO works because the early stage is cheap enough and predictive enough—not because hierarchy is inherently efficient.
The decision is where to spend verification compute
ECHO’s broader contribution is not simply another speculative-decoding speed record. It shows that inference acceleration can come from reallocating authority and frequency across the depth of the same model.
For operators, that reframes the deployment question. A separate drafter is no longer the only way to make speculation cheaper. But neither should the reported speedups be treated as a plug-in expectation. Early-layer alignment, buffer size, model family, workload, kernel implementation, hardware, and serving topology all determine whether the saved full-depth work exceeds the new orchestration overhead.
The next production test is therefore concrete: profile how much full-model verification your workload spends today, measure whether intermediate layers reject candidates cheaply enough, and test whether state reuse remains inexpensive in your serving environment. The paper provides evidence that this trade can work. It does not remove the need to measure the trade locally.
Cognaptus: Automate the Present, Incubate the Future.
-
Ziyang Ma and Zihong Zhang and Zuchao Li and Lefei Zhang and Baoyuan Qi and Siqi Li and Simin Yu (2026). ECHO: Early-layer Collaborative Hierarchical Orchestration with Bonus Logits in Speculative Decoding. arXiv:2609.17241. https://arxiv.org/abs/2609.17241 ↩︎